We Made Our Agent "Remember More." It Got Worse, Not Better.
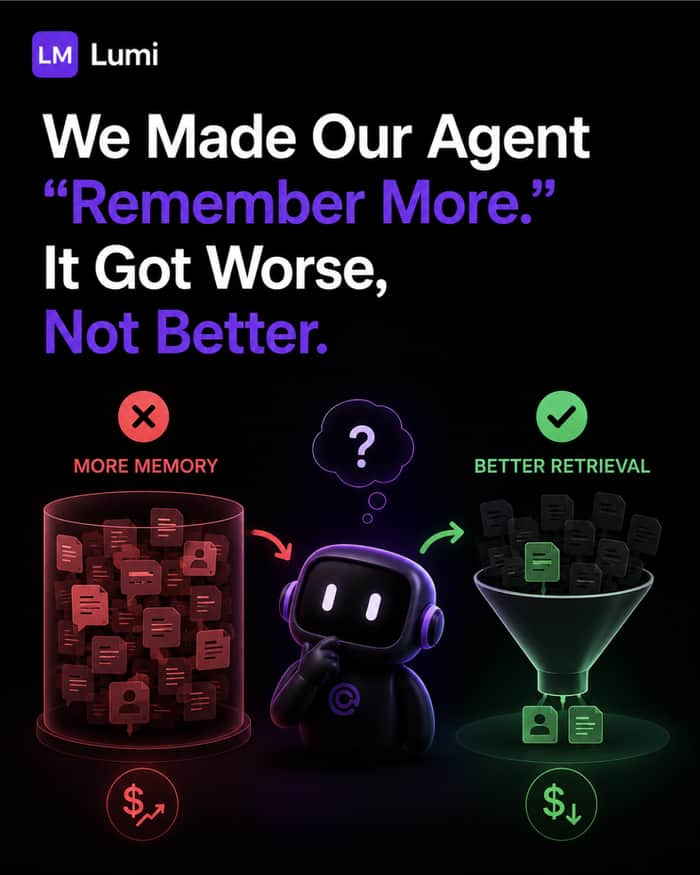
Our fix for "the agent forgot something important" used to always be the same: store more, retrieve more. Increase how much context gets pulled in per call. Felt like the obvious lever.
It backfired twice over. Cost scaled with every message since we were reprocessing the growing history each call, not just the new part. And accuracy actually dropped, not despite more context, because of it, models pay less attention to stuff buried in the middle of a long context window than to what's at the start or end.
The fix wasn't more memory. It was better retrieval. Store everything, sure. But stop dumping the whole history in, pull in only what's relevant to the specific step. Smaller, sharper context beat bigger context on both cost and accuracy at the same time, we expected a tradeoff, not a win on both.
Anyone else learn this one the hard way before switching to retrieval over accumulation?

Thanks for writing this up. Bookmarking it for later.
More history in every call looks like the obvious fix, and your result shows why it isn't. Cost climbs and the one rule that matters gets buried mid-context. A thin, relevant slice beats the whole journal, as far as I can tell. When you retrieve, do you favour what worked last time, or whatever ranks highest right now?
Reading your idea of storing everything but retrieving only what is relevant, I wondered if it would help to put a "librarian" before retrieval.
I think of the AI as the place where thinking happens, not the place where information should accumulate. I would store everything externally, but I also wouldn't have the AI search one big unorganized store directly. I've seen cases where very similar pieces of information seem to get confused with each other, so I would organize the storage first.
I'd do it like this:
First, have an AI read all of the information and create a list of separate items, each with a short note. Don't discard anything. If two items are similar but have meaningful differences, keep them as separate items.
Have another AI look at the patterns in those notes and create the classification boxes it actually needs, with a limit on how many boxes it can create. Also give it an UNKNOWN box for things that don't fit cleanly.
Have another AI sort the original list from step 1 into the boxes from step 2. Don't force uncertain items into the nearest category; leave them in UNKNOWN with their notes. If possible, keep a note for normally classified items explaining why they were placed there too.
Then use the finished shelves as an index for the working AI. Instead of reading or searching the entire raw store every time, it retrieves only the information it needs from the shelves relevant to the current task.
I think steps 1-4 could themselves be automated as an AI relay.
So I would still store everything. I just wouldn't make the AI remember everything.
Build the library first, then let the AI search the library.
If you already have a layer like this before retrieval, I'd be curious how you're organizing it.
By the way, I work on this kind of human-AI collaboration in practice, not just as a thought experiment. If you're curious, feel free to take a look at my site too:
https://www.kaiaspec.com/
The “more memory made it worse” result is interesting.
Did better retrieval improve both cost and task accuracy consistently?