27 real GPU provisioning runs, no cherry-picking — here's what actually happened
Solo founder building Kilawatt Cloud (GPU orchestration for AI agents). Logged every provisioning run against our gateway over two days — real submissions to real providers, timed from request to confirmed-ready, then automatic teardown.
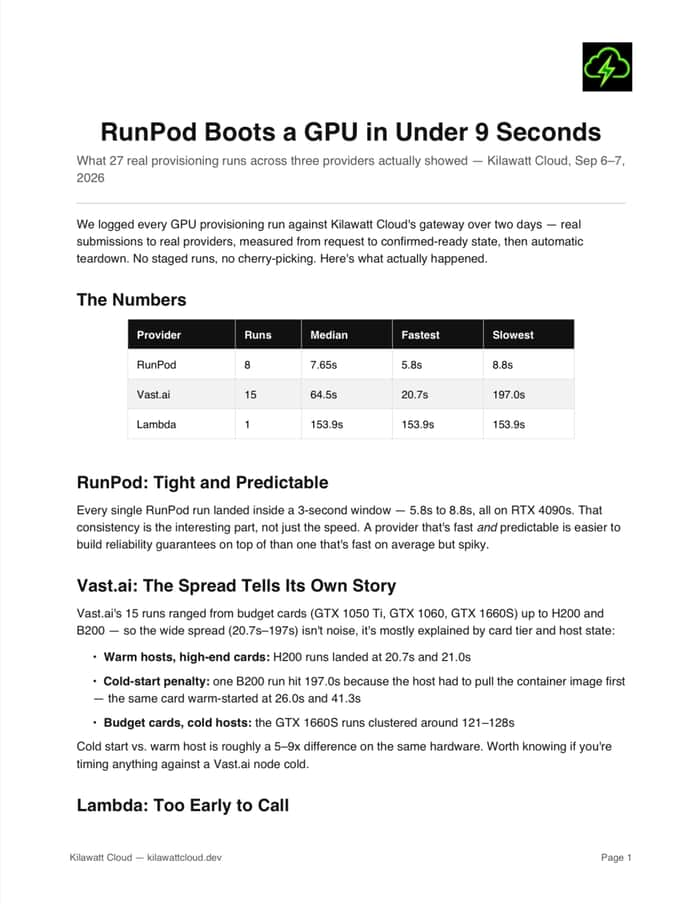
The numbers:
Provider | Runs | Median | Fastest | Slowest
RunPod | 8 | 7.65s | 5.8s | 8.8s
Vast.ai | 15 | 64.5s | 20.7s | 197.0s
Lambda | 1 | 153.9s | — | —
RunPod was the standout — every run landed inside a 3-second window (5.8s–8.8s). That consistency matters more to me than raw speed alone; predictable is what you can build reliability guarantees on top of.
Vast.ai's spread makes sense once you break it down: it spans budget cards up to H200/B200, and cold vs. warm host state is roughly a 5-9x difference on the same hardware. One B200 run hit 197s cold-start; the same card warm-started at 26-41s.
Lambda's just one data point so far — not calling it representative yet.
Full run log with every timestamp is in the attached PDF. This is the kind of number I'd want to see before trusting a GPU cloud's speed claims, so that's what we're publishing.
kilawattcloud.dev
@Kilawattcloud on X if you want to follow along.
