Chinese models now process 50%+ of global dev tokens. We built PandasRouter to solve their biggest international friction.
Hey Indie Hackers! 👋
Over the past few months, if you’ve been tracking AI token consumption stats (like the recent surge where Chinese models like Qwen 3.8, DeepSeek, and Kimi passed 50%+ token share on OpenRouter), you've probably noticed a massive shift:
Global indie devs and startups are aggressively switching to Chinese open/commercial models.
Why? Simple math: 90% lower inference costs for comparable (or superior) reasoning, coding, and multilingual performance.
The Hidden Friction for Global Builders
However, actually integrating models like Qwen, DeepSeek, Zhipu GLM, or Kimi into production outside of China comes with severe headaches:
Cross-border Latency & Regional Throttling: Direct API calls across continents hit unpredictable ping spikes or local rate limits.
Payment & Billing Chaos: Managing multi-currency top-ups and corporate expense tracking across 5+ different model providers is a nightmare.
Failover & Uptime: When a single model endpoint experiences high traffic, your app crashes unless you manually code complex fallback logic.
Enter PandasRouter 🐼⚡
We built PandasRouter to solve this exact bottleneck.
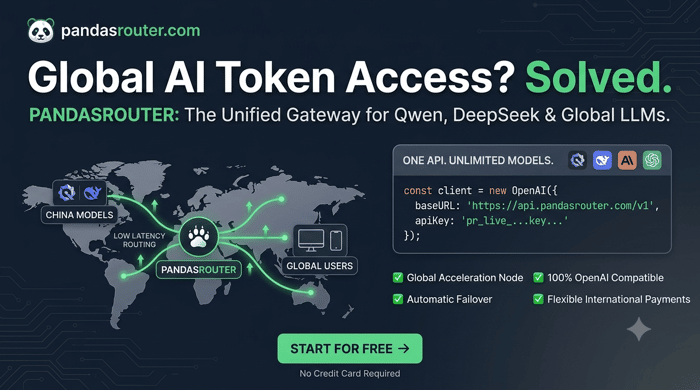
Think of PandasRouter as your unified, low-latency API Gateway optimized specifically for high-efficiency global routing of top-tier models (with standard OpenAI-compatible format):
🚀 Zero-Code Unified API: Drop-in replacement. Switch between Qwen, DeepSeek, Claude, or GPT-4o by changing a single line of code (base_url).
⚡ Smart Cross-Border Acceleration: Intelligent edge-routing nodes route requests through the fastest endpoint, cutting response times by up to 40%.
🔄 Automatic Dynamic Failover: If one provider hits a rate limit or goes down, PandasRouter instantly reroutes your prompt to a backup node without dropping the connection.
💳 One Balance, All Models: Unified credit pool with flexible international billing (Stripe, Crypto, invoice support).
Built for Indie Hackers & AI Startups
Whether you're building automated workflow agents, translation pipelines, or coding copilots, you shouldn't have to worry about infrastructure friction when scaling.
We’d love for the IH community to test it out!
🔗 Try it here: c c
Drop your thoughts below—what models are currently powering your main stack, and what’s your biggest bottleneck when routing AI requests? Happy to give extra free testing credits to anyone replying! 👇
