I built FreshCtx to stop stale agent actions. Then I found a harder failure: the action still happened.
A couple of weeks ago I posted FreshCtx here.
The problem was pretty narrow:
an agent reads a balance, approval, inventory level or some other live state, makes the right decision, and then reality changes before the action executes.
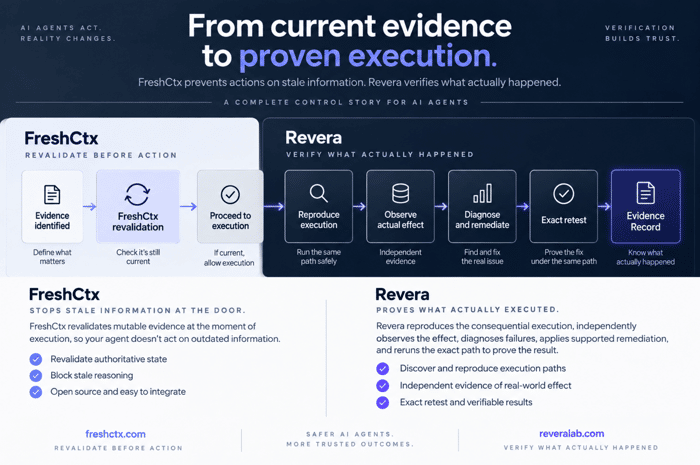
FreshCtx revalidates the evidence at the action boundary.
That part worked.
But the discussions here exposed a problem I couldn't stop thinking about.
What if the control is correct, but the action still happens?
Imagine this:
The agent decides to make a payment.
FreshCtx checks the evidence.
Or a human approves the action.
The tool runs.
The payment succeeds.
Then the response times out.
The agent sees:
PAYMENT FAILED
Reality says:
PAYMENT HAPPENED
What should the agent do now?
Retry?
If it retries, you may have two payments.
And that made me realize FreshCtx shouldn't try to solve everything.
FreshCtx asks:
Is the evidence behind this action still current right before execution?
I built a separate product for the next question.
It's called Revera.
Revera asks:
What actually executed, what effect can we establish independently, and if we fix the problem, can we prove the same execution path now behaves correctly?
The flow is roughly:
discover → reproduce → observe → diagnose → remediate → exact retest → evidence
One rule became important while building it:
The system under test should not be the only authority on whether its own action succeeded.
If the agent says the action failed but the external effect occurred, I want both facts preserved.
If we can't establish what happened, I would rather see UNVERIFIABLE than manufacture a convenient answer.
Revera is live now:
https://reveralab.com
I'm looking for a small number of people building agents that actually change something:
payments, infrastructure, customer records, access, deployments, bookings, approvals, workflows.
I don't need a polished integration.
Give me one consequential action or one public repo and let's see what Revera can actually establish.
And I'm particularly interested in cases where you think it will fail.
Question for builders here: what is one action in your agent that you would absolutely not trust it to retry blindly?

Oof, "the action still happened" hit hard. That's the nightmare version, you can replay state all day but you can't un-send money.
Ran into the same wall from the payments side. Idempotency keys and versioned state are great, but they guard the request, not the consequence. What finally worked for us was splitting authorization from execution completely. Lock the spend against a deal ID up front, so a stale retry just finds an already-used (or expired) authorization instead of fresh money to move. Basically your pessimistic lock, but on the money instead of the state.
Genuine question: when the external side effect already went through, do you reconcile after the fact, or is it prevention all the way down?
Your deal-ID approach sounds like a good candidate for an independent test. Would you be open to putting a small, scrubbed version through Revera with us?
We’d test lost responses and concurrent retries around authorization consumption, then give you the evidence of whether a second payment can get through—or where the outcome remains uncertain. No production access needed; a minimal mock is enough to start.
Is that boundary fully settled for you now, or does it still cause debugging or reconciliation work?
Really appreciate the offer, and yeah, I'm up for it. A minimal mock is cheap to put together, and I'd genuinely like to see what your harness finds. The concurrent retries case especially, that's the one I lose sleep over.
One honest caveat: our rails are simulated right now, so the mock tests the authorization logic, not real money movement. If that's still a useful input for Revera, happy to do it.
To your question: the boundary is settled in the sense that no double-spend has gotten through in our protocol runs. The debugging didn't disappear, it moved. Now it's authorization lifecycle stuff, expiries, orphaned locks, the authorizer going down mid-deal. Less scary than money moving twice, but still real work.
I can put the mock in a gist if that's easiest.
A gist would be great. Simulated rails are useful here—we’ll keep the conclusions scoped to the authorization logic.
Please include the dependencies and run command, how to trigger the concurrent retries, and what we should inspect to tell whether the same authorization was consumed more than once. If there’s a particular timing or failure sequence you’re worried about, include that too.
No need to integrate Revera on your side yet. I’ll review the mock first, confirm the test scope with you, and then share the results and supporting evidence. Let’s start with concurrent retries and leave expiry or authorizer failures for a follow-up.
The payment example scales down further than people might think, which I think helps your case. I ship a small desktop app with metered AI actions, and the same divergence shows up at tiny stakes: the server debits a usage credit, the action completes, and the response dies on a flaky connection, so the client shows a failure while the meter recorded a success. Let the client retry blindly and the user pays twice for one result. Nobody is going to build an observability stack around that, and nobody is going to notice it either, until the support email arrives.
What fixed it was refusing to let the client's view count as evidence at all: the server is the only authority on whether a request consumed quota, and a failed delivery reconciles into a refund rather than the client deciding anything. Which is a home-made single-system version of your principle that the actor should not grade its own homework.
The question I never solved generally, and I suspect it is your hard one: what does Revera do when the system acted on offers no independent read path? A payment processor lets you query the charge afterwards, but plenty of APIs are effectively write-only, and the only witness to what happened is the same endpoint that timed out. Do you require an evidence source before onboarding a workflow, or degrade gracefully without one and say so?
That is exactly the hard boundary.
I don’t think Revera should pretend it can prove an outcome when the underlying system gives us no independent way to observe it.
So I would separate three cases:
For a write-only API, I would rather tell the operator “we cannot independently establish whether this side effect occurred” than infer an outcome from the same endpoint that produced the ambiguity.
Your metered desktop example is actually a very good bounded Revera scenario because it has a clear authority: the server-side usage ledger.
If you are open to it, I’d like to reproduce the pattern with a minimal version:
server consumes credit → action completes → response is lost → client sees failure → retry becomes possible.
Then Revera can record what the client believed, what the authoritative ledger says happened, and whether the retry creates a second charge.
No production code or credentials needed. A small mock of the behavior would be enough.
Idempotency keys help, but only if every boundary honors the same key and keeps a durable lookup. The worst case is a timeout after the provider accepted the request but can't confirm that it did. I would treat "unknown, do not retry automatically" as a first class result. Then give the operator the exact external reference needed to resolve it. That approach is less magical than automatic recovery, but much safer for payments and bookings.
I agree with treating UNKNOWN as a first-class result.
The dangerous shortcut is turning “I didn’t receive confirmation” into either “nothing happened” or “retry.”
For Revera, I’m separating:
confirmed effect
confirmed no-effect
unknown / insufficient authoritative evidence
duplicate effect
The operator reference is important too. If the outcome is unknown, the system should preserve exactly what is needed to reconcile it later rather than invent confidence.
If you have a small timeout-after-acceptance case from payments, bookings or another API, I’d be interested in running it as a bounded Revera scenario and reporting the observed classification back here.
I’m specifically looking for cases where the provider may have acted but the caller cannot safely know whether to retry.
Anything that sends an irreversible message or moves money — for us that was outbound notifications, where a timeout retry means a duplicate the user actually sees. We ended up requiring an idempotency key from the caller and keeping writes read-only until there's an explicit per-call grant, so a blind retry fails loudly instead of firing twice.
Outbound notifications are a great example because the failure is immediately visible to the end user.
The interesting test for Revera would be:
send accepted → response lost → caller believes failure → retry attempted
Then compare two controls:
without durable idempotency / per-call grant → duplicate notification
with them → second execution is rejected or reconciled
That gives us something measurable rather than just saying “idempotency is good.”
If you are open to sharing the minimal shape of your retry flow, I’d like to reproduce that scenario and send the result back here. No production system needed — just the sequence, expected state and where the idempotency record lives.
What I’m trying to build now is a public record of these failure patterns and whether the selected control actually changes the outcome on replay.
The failure mode is much more consequential than stale context, but the key signal seems to be whether it shows up in real agent systems. Have builders brought you actual incidents where execution and reported outcome diverged, or is that still the hypothesis you’re trying to validate?
One clarification because I know the obvious question will come up:
Revera is not meant to replace observability or tracing.
A trace can tell me that the agent called charge_customer and received an error.
The question I'm interested in is whether the customer was actually charged.
That distinction sounds small until an autonomous agent decides whether to retry.
If anyone has a public repo where this kind of ambiguity can happen, send it over. I want the first external runs to be systems we didn't build.