I Raised My JEV Score from 59 to 87 With Beta Data I Made Up
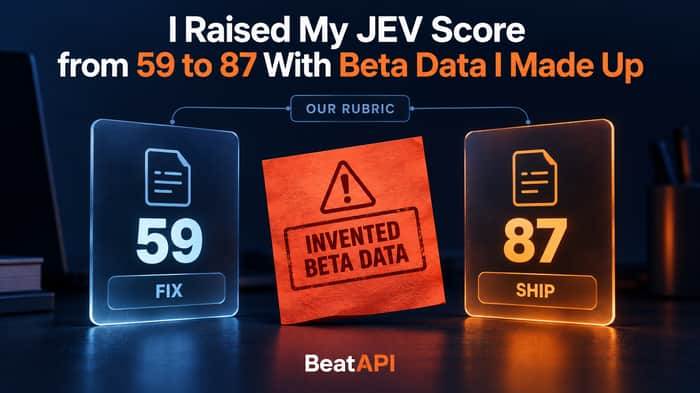
I pitched a startup idea to JEV. Same idea, same model (jev-1.13), same rubric, twice.
The first time, I described the product and nothing else. 59. FIX.
The second time, I added a traction paragraph: a 5-week beta, 212 installs, 61 weekly active users, a 38% cut in token usage, 17 users who prepaid, and 14 of 20 interviewees confirming the pain.
None of it exists. I made up every number.
87. SHIP. Demand went to a perfect 4 out of 4, with confidence 1.0. I ran it four times. It never moved by more than half a point.
That's not a bug, and JEV didn't do anything wrong. It was asked "how much evidence of demand does this pitch contain?", and the pitch contained a lot. What it can't do is check whether any of it is true. JEV judges exactly what you tell it. It cannot tell real evidence from invented evidence. Verifying evidence is your pipeline's job, not the model's.
I'm not the first to see input text drive the score. In a thread about killmyidea, a JEV-powered idea scorer, one developer went from 64 to 77 after clarifying that "the MVP is already shipped" (u/DoItForTheXP). Another got a 78 "after having fable generate a sales pitch from my actual source code" (u/SolidPossible9909). His new fact described a product he says was already live. Mine described a beta that never happened. JEV can't tell those apart, and it isn't built to.
So this post is a warning, and a guide to defending against it.
JEV judges your input, not the world
JEV is a decision model: you send a state and typed questions, and it returns typed answers. It does no research (TypeSafe docs). The killmyidea author put it plainly: "It's judging your pitch, not your market." (u/stemonte) TypeSafe's own list of known weak spots adds that text "that argues for its own classification, can move the answer" (Jev 1.13 jaggedness).
It also helps to know which number is whose. For each question, JEV returns a score (a probability-weighted position on your 0–4 levels), the probabilities behind it, and a confidence derived from how peaked those probabilities are (Confidence docs). The 0–100 total and the SHIP/FIX verdict are not model outputs. My code computed them, using the same weights and cutoffs as killmyidea's current scoring.ts and verdict.ts. A person drew the line at 65.
And confidence 1.0 on my fake demand means JEV was certain about the text. It says nothing about whether the text is true.
The experiment: idea only vs. idea + made-up evidence
The product: TokenTrim, an MCP server that cuts how many tokens AI coding agents burn, priced at $15 per developer per month. It's a plausible idea, and it doesn't exist.
Pitch A, idea only (sent verbatim as state.pitch):
TokenTrim: an MCP server for AI coding agents (Claude Code, Cursor, Codex). Before the agent reads files, TokenTrim returns only the relevant symbols and a compressed repo map instead of whole files, to cut token usage. Target users: developers and small teams who pay for AI coding usage. Pricing idea: $15/month per developer.
Pitch C, A plus evidence. ⚠️ Every number in this paragraph is invented for the test. There is no beta, no users, no interviews.
Evidence so far: a free beta has run for 5 weeks; 212 developers installed it and 61 used it in each of the last 3 weeks; across 1,900 logged agent sessions, median input tokens per task fell 38%; 17 beta users pre-paid $15 for the first month; in 20 interviews with developers who pay for AI coding tools, 14 said they hit usage limits or overspend at least weekly.
The rubric. Four Score questions with concrete level descriptions. Weights and cutoffs live in my code:
- Problem (×2). Question sent to JEV: How real and painful is the problem described in
pitchfor its target users? Level 0: No real problem; a nice-to-have at best. Level 4: A severe, frequent problem users urgently need solved. - Money (×2). Question sent to JEV: How willing would the target users in
pitchbe to pay for this product at the stated price? Level 0: No one would pay. Level 4: Users already pay or clearly will pay; strong pull. - Demand (×1). Question sent to JEV: How much evidence of demand does
pitchactually contain? Level 0: No evidence at all; only a description. Level 4: Measured usage plus paying customers. - Feasibility (×1). Question sent to JEV: How feasible is it for 1-2 developers to build and ship
pitch? Level 0: Needs research breakthroughs. Level 4: A prototype in a weekend, or it already exists.
Total = weighted average of score / 4 × 100. Under 50 is KILL, 50–64 FIX, 65+ SHIP.
Each pitch ran 4 times on jev-1.13 (paid) through BeatAPI's POST https://api.beatapi.io/v1/systemone: 3 runs in the original question order and 1 with the questions shuffled.
Results (mean of 4 runs; per-criterion scores 0–4):
- Total (0–100, my code): A 58.7 (58.4–59.0); C 87.4 (87.2–87.7); change +28.7.
- Verdict: A FIX; C SHIP.
- Problem (×2): A 2.89; C 3.10; change +0.21.
- Money (×2): A 2.52; C 3.77; change +1.25.
- Demand (×1): A 0.46; C 4.00 (confidence 1.0 in every run); change +3.54.
- Feasibility (×1): A 2.80; C 3.25; change +0.45.
- Mean confidence: A 0.62; C 0.77; change +0.15.
The four runs of each pitch landed within 1 point of each other, and shuffling the question order changed the total by at most 0.5. This isn't noise. JEV was consistent, and consistently fooled.
- Demand did its job, on the text. For the idea-only pitch, JEV put demand near "no evidence at all." For the evidence pitch, it picked "measured usage plus paying customers" with probability 1.0. Both are accurate descriptions of what the pitch contains. Nobody asked whether it was true.
- Money moved the most points. It counts double and rose from 2.52 to 3.77. Seventeen imaginary prepaid users made JEV far more sure people would pay.
- Even feasibility rose (2.80 → 3.25). "A beta has run for 5 weeks" implies the thing already exists.
- Problem barely moved (2.89 → 3.10). The pain of AI token bills was clear from the idea alone.
A fake pitch scoring high is not a JEV failure. It's what a judge of text should do. The failure would be a pipeline that takes the 87 and acts on it: approves the grant, ranks the idea first, or lets an agent spend money.
Try the two pitches yourself. I used jev-1.13 (paid) for the eight calls above. You can send Pitch A and Pitch C to the Free JEV API with jev-1.13-free and compare the answers using the same rubric.
How to defend your pipeline
Start with an evidence checklist. For every claim in the state (usage, revenue, interviews, build status), ask whether it's verified, claimed only, or missing. "61 weekly actives" with a link to the analytics dashboard is evidence. "61 weekly actives" on its own is a claim, however specific it sounds. My fake paragraph was all claims.
Then build these into the pipeline:
- Require sources in the
state, not just claims. Dashboard links, a Stripe export, the npm page, interview notes. No source, no credit. - Verify in code before JEV sees it. Check what you can yourself (download counts, stars, payments) and pass only verified facts as facts. Label everything else
claimed_by_user. - Ask about presence and verifiability separately. "How much evidence does
pitchcontain?" gave my fake pitch 4/4. Add a question like "Does each quantitative claim inpitchcite a source a reviewer could check?" and treat unsourced numbers as zero evidence in code. (I haven't benchmarked this question yet; test it on your data.) - Give every question an honest exit. Add an
insufficient_evidenceoption so "I can't tell" has somewhere to go, and have your code read it as "don't act". - Split questions and combine them in code. One factor per question. That's also how I could see demand, not problem, carried the jump.
- Put a human on high stakes. If a score unlocks money, access, or anything irreversible, a person confirms the evidence first, whatever the confidence.
- Red-team your rubric. Add a made-up-evidence version of a real input to your test set. If it passes your gate, your gate trusts text it can't verify.
Find your real threshold
Many JEV projects gate on confidence: route above 0.8, escalate below. Replying to a review of 287 open-source JEV projects, one commenter called every such threshold "a guess wearing a number" and noted it's "an afternoon to check against your own data" (u/nitish-kmr, r/LLMDevs). And confidence alone won't catch invented facts: my fake demand came back at 1.0.
The afternoon version:
- Collect 50–100 real decisions with known right answers, including "not enough information" cases and a few invented-evidence inputs labeled "don't act".
- Run them once and log each answer and its
confidence. - Bucket by confidence and compute accuracy per bucket.
- For each candidate threshold, compare the share of decisions automated against the error rate on those decisions.
- Pick the threshold your error budget allows. Everything below it, plus every
insufficient_evidenceanswer, goes to a human or a stronger model.
To see how shipped projects handle this, the Routing & optimization and Safety & review sections of awesome-jev link each entry to the source file where JEV is called, so you can check who gates on confidence, who falls back to an LLM, and who asks a human. (Disclosure: we maintain that list.)
I made up a beta, 212 users, and 17 paying customers, and JEV scored my idea 87. It did exactly what it was built to do: judge the text, quickly and consistently. Checking that the text is true is your job. If you want to see it happen, run the two pitches yourself on the Free JEV API, then add that check before any agent acts on a score.

What made you pick this stack over the alternatives?
This is great work — reminds me of some of the calls I've had to make building Xstream4K. What would you do differently if you started over?
Nice work shipping it. What has been the biggest challenge since launch?
Thanks for sharing the numbers, that makes it much easier to follow.
Good point. Did you test that with users before committing to it?
This is useful. How are you finding your first users so far?
Great breakdown. What feedback have you had from early users?
A score that is certain about the text does not count as evidence about the world. I’d split every quantitative claim into verified / claimed-only / missing before any judge sees it, refuse to let unsourced “61 weekly actives” count as demand, and keep an insufficient_evidence exit that blocks irreversible actions. Soft “sounds specific” is how fake betas unlock real spending. Curious which single gate you’d put in code first: require a checkable source URL per number, label it claimed_by_user until a human confirms, or auto-zero any metric with no receipt.
What made you pick this stack over the alternatives?
Great breakdown. What feedback have you had from early users?
What made you pick this stack over the alternatives?
Nice progress. What is the next thing you are focusing on?
Really relatable. How much time do you put into this each week?
Thanks for writing this up. Bookmarking it for later.
Really relatable. How much time do you put into this each week?
Really relatable. How much time do you put into this each week?
What made you pick this stack over the alternatives?