I told a founder to get listed on the review sites. Her report showed AI was citing her competitors' homepages.
I build Orbator. It measures whether AI assistants recommend your product, and traces which sources they read before answering.
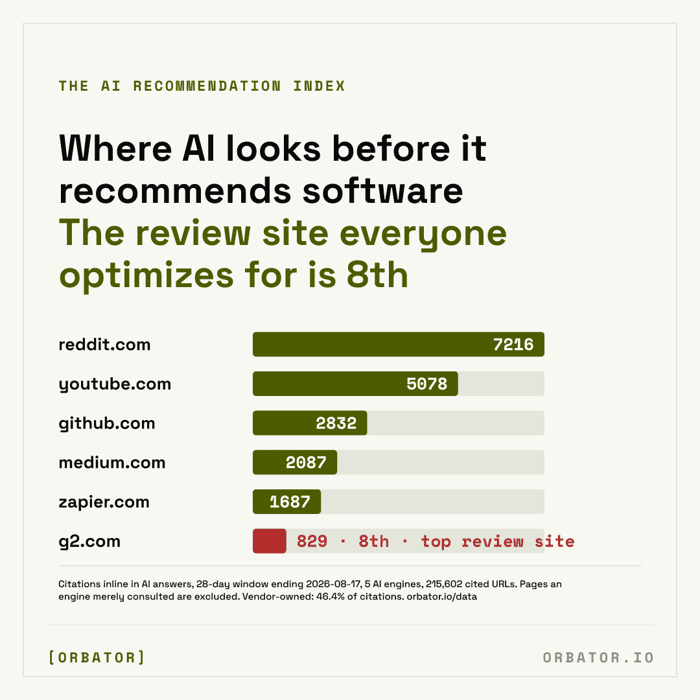
A founder emailed last week asking which two or three placements would move the needle for her consumer money app. I assumed the answer was directories and review sites, because that is the advice everyone gives. My own data should have warned me. Across the software categories I track, the most cited domains are reddit and youtube. G2 is the biggest review site, close to four times Capterra, but it sits eighth overall and reddit gets cited almost nine times as often.
Looking into the detail of her actual report changed that. For the question that matches her differentiator, an app that works without connecting your bank, the engines had cited three pages. After checking all three, every one was a competitor's own website. Not a review site, not a listicle. Just products like hers, being used as the source. One of them runs almost exactly her pitch, a 0 to 100 money score with no bank linking, and it gets cited while she gets nothing.
So the assumption was wrong. The gatekeeper was not an editor at a review site. It was her own homepage. Those competitor pages get cited because they say it plainly, right there on the page: "never link a bank", "no bank linking required". Her site says it once, as a feature bullet.
Here is what I had missed. The directory playbook is real, it is just a B2B playbook. When someone is buying a tool for work there is a G2 page to lean on. For consumer apps there is no G2, so the engines fall back on whoever explains the category best, and that is usually a competitor. I had one dataset, I had not even read it closely, and I assumed it applied everywhere.
The test I use now: look at who is already getting named. All household names, skip that question. Apps you have never heard of in there, the slot is open.
Has anyone here checked which sources the AI answers in your category are actually built on?

The homepage finding matches what I got on my own site, from the other direction. I run an AI visibility tool and I checked it against itself first: fifteen non-branded prompts, an honest zero. The domains cited instead of me were other vendors in the same race, not directories, which is your 46 percent in miniature. The useful part was that the list of who got cited turned into the task list.
One thing I have not seen raised in this thread, and it sits underneath every number any of us report: where the prompt was asked from.
Asking in a logged-in ChatGPT session with memory on does not measure the web, it measures your account. I have a run where my own brand appears inside a comparison table for a prompt that never named it, pulled out of account memory rather than retrieved. Turn memory off, ask the same thing, and it is gone. That is the single easiest way to convince yourself you are visible when you are not.
The second layer is variance. Three clean runs of the same prompt on the same day returned three different source sets for me. So a single check is not a measurement, and a month-on-month drop is not a drop until you can go back to what was actually said behind both numbers.
Which makes me curious about your pipeline, since your dataset is the largest one in this conversation. Does it run through the APIs with a fresh context per prompt? If so, your numbers avoid the contamination problem entirely and that is worth saying out loud, because most people reading this thread will go and check by hand in a logged-in session and get a flattering answer.
I wrote up the memory contamination case with the screenshots here, if it is useful: https://ivabot.xyz/blog/how-to-measure-brand-visibility-in-chatgpt
This is exactly why we measure through the APIs with no account and say so in our methodology. A logged in session is a sample of one person's ChatGPT. Your brand appearing in a table from memory rather than retrieval would poison any handrun study silently.
It also connects to whats going viral on X. The Reddit-collapse charts going around are measured on ChatGPT Search, the app surface. Our API runs show no collapse at all, Reddit held its usual share through the same days. App, API, and now logged in with memory are 3 different instruments giving 3 different readings of "what ChatGPT says." Most published numbers in this space never state which one they used.
Respect for testing your own tool against yourself and publishing the zero. What did you do with the task list the citations gave you?
I treated the cited domains as competitors to audit rather than a list to copy. For each one: structure of the article, depth and length, how much of the topic they actually cover, domain age, backlinks, how known the brand is. That tells you fairly quickly which citations you can realistically take and which ones are there because the domain is fifteen years old and everyone links to it.
Then I rewrote a few of my own articles to match what the winners were doing, as a test, and left the rest alone. Results not in yet, so I have nothing to report on that part.
The distinction that came out of it: some citations are winnable with better content on the same question, and some are not winnable at any content quality because the source is cited for authority rather than for the answer. Worth separating the two before you spend a month writing.
Your winnable versus authority split shows up in our page fetching too. Authority citations have a tell. Old institutional domains get cited without ever being quoted, irs.gov in our accounting runs, a tourism board in our local ones. The winnable slots look different, the engines lift actual sentences from those pages. So a rough test that falls out of it, if they quote the page's own words the slot can be taken with better content, if they cite without quoting you are looking at authority and should spend elsewhere. Post the rewrite results when they land.
Good tell, I will check it against our stored answers.
One caveat: how much an engine quotes at all varies by engine. Perplexity lifts sentences readily, ChatGPT paraphrases even when it clearly has the page. So the same slot could read as winnable on one and authority on the other.
Will post the rewrite results when they land.
Fair catch, the test needs an engine baseline. Perplexity quotes so freely that quoting tells you little there, and ChatGPT paraphrases enough that absence of quoting proves nothing. The version that survives your caveat is relative, compare how the engine treats that page against how it treats pages generally, not against zero. We fetch the cited pages anyway so per engine quote rates are computable on our side, I will see what the baselines look like. Good luck with the rewrites, still want the results whichever way they go.
Before her rewrite ships, run the same question set a few times against the frozen page and see how much the cited set moves on its own. The engines resample, so part of that weekly curve is churn you'd get with nobody touching anything, and week three's movement isn't attributable to her copy without that baseline.
Is the plan a single weekly run, or several per week so the curve has an error band?
Founders may struggle with AI answers as an acquisition channel, facing solid on-page SEO yet remaining invisible to the sources the model cites. How are you distinguishing between "not cited" and "cited but the source isn't attributed back to the founder's page?"
Directly, because we fetch every page the engines cite and store the text next to the answer. That turns your two states into three, and the middle one is the interesting one.
Not read at all: your domain never appears in any citation list. We recently reran seven small products through their full question sets and three were in that bucket, zero cited pages anywhere. For those founders copy changes are pointless until something they own gets into the reading list at all.
Cited but ignored: your page is in the reading list and the answer skips you anyway. We measured this at publisher scale. One Miami outlet's brunch coverage was cited in the sources and followed zero times across 15 recommendation slots, while the same outlet's old pancakes listicle ran a 39 percent follow rate, 24 of 61 recommended spots traced back to its pages. Same domain, same month. Citation on its own is closer to decoration than influence.
Cited and carried: the recommendation traces to a page that names you. That trace is the only one of the three I would spend money moving.
Galyna upthread has the cleanest label for the split: pages you get quoted from are winnable, pages that get cited but never quoted are authority. We are building exactly that distinction into the reports.
The B2B vs consumer split is a real distinction that almost nobody makes when giving AI visibility advice. The directory playbook gets repeated because it works — for one context — and then gets cargo-culted into every other one.
The competitor homepage finding is the part that should make founders uncomfortable. Those pages aren't optimized for AI citation deliberately, they just describe what they do clearly and specifically. "No bank linking required" is three words that answer the exact question a buyer types. Most homepages bury that or abstract it into benefit language that sounds good to humans and means nothing to a retrieval system.
The test you describe — look at who's already getting named — is the right starting point. If you see a mix of unknowns in the cited sources, the slot is genuinely open. If it's all G2 and TechCrunch, the barrier is authority, not copy.
What are you seeing in terms of how quickly a homepage change propagates into citation? That's the part I'd want to understand — whether a founder who fixes the copy this week sees movement in weeks or months.
Honest answer, the measured base for that is one natural experiment plus one in flight, so hold it loosely. jkjone further down the thread moved the differentiator into hero copy and started showing up a few weeks later, which roughly matches how long the engines take to refresh what they read. The founder from the post is the live one. Her rewrite has not shipped yet, and when it does I will rerun her questions weekly and post the curve here whichever way it goes.
One thing I can already say from fetching the cited pages, the lag has two stages. If the engines already read your page, a copy change seems to ride their refresh cycle, so weeks. If your page is not in the reading list at all, the rewrite does nothing until it gets read. We recently reran seven small products through every question set and three of them appeared nowhere, not one cited page. For those three the copy was never the constraint. Worth checking which stage you are in before timing anything, ask your buyer question and see whether anything you own shows up in the citations at all.
The distinction between discovery footprint vs. refresh lag is a great breakdown.
For early-stage products stuck in Stage 1 (not in the reading list at all), the bottleneck is usually zero external footprint. LLMs tend to pick up the brand through directory citations, launch posts, and community threads long before they index the root domain.
We see this exact pattern a lot while building zarek.tech (launch automation/auditing tool)—founders spend weeks tweaking hero copy, but until they seed structured listings across external channels to get verified footprint, the engines simply have nothing to cite.
Looking forward to seeing the data from that rerun once her changes go live.
Same pattern here: pages that state the differentiator as a plain verdict up top get cited, feature-bullet pages don't. We've been tracking which pages AI assistants actually cite vs which ones founders think they cite — the gap is usually bigger than people expect. The homepage rewrite is the cheap win; measure what got cited before changing anything. We built a small tool for the tracking side: https://amami.dev
The gatekeeper part rings true. Spot-checking how ChatGPT answers 'best app for X' queries, I've run into the same pattern - the pages that get cited state the differentiator as a plain sentence up top, not buried as a feature bullet. Did the founder end up rewriting her homepage, and did citations actually pick up after?
Not yet. She asked for the full breakdown after the report and we are working through it together, the rewrite has not shipped. When it does I will rerun the same questions on a weekly loop and post what happens here either way. Hers is the cleanest natural experiment. You are the closest thing to a finished version of it so far, which is why I asked about your setup. The offer stands, tell me the category and I will run it both ways so you can see where you sit against those two competitors now.
There’s a second gate after “can the model quote this page?”: can it recommend the claim without hedging. I built Andrew’s Freebies, an agent-friendly search, and the implementation choice I keep coming back to is attaching the rule, catch, and primary source to every result.
For the money app, I’d test a compact claim block: “No bank connection required,” who it applies to, price, and links to the security or methodology evidence. Plain language may get the page retrieved; attached evidence gives the agent something defensible to say.
The hedging gate is real and mostly unmeasured, everyone counts citations and stops. Your claim-block structure is testable on our side. We already fetch the cited pages and check whether the recommended names appear on them, and extending that to whether the page carries evidence next to the claim is the same machinery pointed one layer deeper. If you have examples where adding the evidence block changed how an agent phrased the recommendation, feel free to share.
This matches what I keep seeing. A listing on a review site is a weak entity signal if the page itself has no verdict, no comparable pair, and no first-party notes. Models quote the page that already made a decision. Treat the listing as a pointer, then put the actual claim on a comparison or review you control. Ask the same buyer question in ChatGPT and Perplexity a week later and see which URL they cite. If it is still the competitor homepage, the listing did not create a citable page.
The re ask loop you describe is the whole discipline in one sentence, and almost nobody closes it. One addition from our data, when the listing does not create a citable page, the citation usually does not vanish, it stays with whichever older page already made the decision. The 2020 listicle in our pancakes example has outlived six years of newer content.
This is a useful distinction. I would treat the homepage copy as the next small experiment, not just an SEO cleanup.
For the founder in your example, I would rewrite one section around the exact narrow phrase people would ask an AI assistant, like "budgeting without linking a bank," then watch two things: whether the AI citations change, and whether human visitors understand the page faster.
If both improve, that page becomes the asset worth promoting. If citations improve but buyers still bounce, it is probably just clearer to machines than to people.
The two metric version is the right experiment, and @jkjone a few comments up already ran half of it. Moved the differentiator into hero copy and the citations followed within a few weeks. Nobody has paired it with the human half yet. My read from fetching the winning pages is that the divergence you describe is rarer than you would think, because pages that win citations are written in the words buyers actually type, and that usually reads clearer to people too. But that is a read, not a measurement, and your bounce check would settle it. The citation half is easy to watch weekly, the human half is ordinary analytics.
Promised results from the new budgeting category, first pass: 28 answers, four engines, so structure rather than rates.
The broad question, best budgeting app, is carried by financial media: forbes, cnbc, nerdwallet, pcmag, wsj. The narrow question, budgeting app that works without linking a bank, is carried by the product pages of apps I had never heard of before this run: pocketclear, moneypeas, getfinny, waypointbudget, plus reddit at three times the share it gets on the broad question.
So @d1nz called it: two different competitive sets inside one category. On the broad question you are competing with Forbes for attention. On the narrow one the slot is held by whichever small app states the capability plainly, which is exactly the situation the original post described, now reproduced in a fresh category on demand. Deeper runs land over the coming weeks and go into the public index once the sample clears our publish gate.
This is a fascinating dataset. The gap between what founders think AI assistants cite and what they actually cite is probably even wider in the AI-generated app space.
I've been auditing codebases built with Bolt, Lovable, etc. A pattern I'm seeing: founders spend time on directories and review sites for visibility, but their actual technical footprint (GitHub commits, dependency security, how their API handles rate limits) is what determines whether an AI assistant recommends them over a competitor.
Your tool measures citation. The corollary question for builders: are you building something an AI would recommend if it actually understood your product?
Half of that matches what we measure and half I would push back on. github.com is the third most cited domain across our software categories, 2,832 citations in the last 28 days, so for developer facing tools the technical footprint absolutely gets read. Repos, readmes and docs are corpus like everything else. But the engines are not inspecting rate limit behavior or dependency hygiene. They read what is written. A clean API with no page explaining it is invisible, and a mediocre one with plain docs gets cited. Worth checking on your own audits: ask the engines a question the product answers and read what they cite. The repo often shows up before the homepage does.
The B2B/consumer split may not be what's doing the work here.
I built a semantic core for a B2B niche — promoting SaaS, about as B2B as it gets. 2,025 autocomplete expansions off 45 seeds, 261 phrases after dedup, 139 that belong to the market. Different instrument from yours, so take it as adjacent evidence rather than a replication: Google autocomplete and SERPs, not AI citations.
The shape came out the same as yours anyway. The pages holding the head terms — saas directories, product hunt alternatives, how to promote your saas — are content marketing published by competing tools. Not G2, not the directories themselves, even though G2 covers that category thoroughly and always has.
So "consumer apps have no G2" doesn't look like the condition. The condition looks more like: does an independent corpus exist for that specific question. Nobody except vendors writes down what a directory will actually ask you for before it accepts you, so vendors get cited, B2B or not.
One thing from that data that might change how you read the reddit number. Across separate clusters, "reddit" keeps appearing as a suffix people type themselves: how to market a saas product reddit, saas directories reddit, product hunt alternatives reddit, how to promote your saas on reddit. Some share of reddit's citations is downstream of humans explicitly asking for reddit, because they have already decided vendor pages are not worth reading. That makes it an odd target — there is nothing to get listed on. There is only being the thing someone names.
And on her actual fix: what won wasn't a domain, it was a sentence. "No bank linking required", in the words the question gets asked in, against her one feature bullet saying the same thing quietly. That page is the one she already owns.
Late follow-through on this exchange. Your genre-gap line kept proving out, so the split is measured directly now, broad and narrow labeled on every question. I put up an offer post where I run any category both ways, and the first seeded run shows exactly the pattern you described, the narrow question carried by product pages where no independent corpus exists. Name a category there and I will run it: https://www.indiehackers.com/post/you-told-me-narrow-and-broad-questions-have-different-gatekeepers-name-your-category-and-ill-run-it-both-ways-63413ba42a
The independent-corpus condition fits a test I ran for d1nz above: accounting software, a category G2 has covered thoroughly for a decade. On the narrow problem-solving questions the top cited pages are quickbooks, xero, pilot, bench and rippling product pages plus irs.gov, and G2 is absent from the top twelve. Thorough coverage, zero presence on those questions. Which is your mechanism exactly. Nobody except the vendors writes the operational detail down, so the vendors get cited, B2B or not.
The typed "reddit" observation is a confound I cannot separate on my side, since I see what the engines cite but not what the user asked upstream, so I am glad someone with query data flagged it. What was your rule for the 139 of 261 that belong to the market? Drawing that boundary is the hard part of authoring our question sets too.
A manual pass, not a classifier. Worth saying plainly, since you're asking about method.
The rule was about the person rather than the topic: keep the phrase if whoever typed it already has something to promote, drop it if they are still learning what the words mean. That removed the definitional cluster — what is saas marketing, what is b2b saas marketing, is saas b2b or b2c — even though a couple of those carried the highest persistence in the whole set. Students and job seekers, not buyers.
The second reason for dropping them is the one that might transfer to your question sets. It isn't only that they don't convert. It's that they wreck the measurement: definitional pages pull volume, and once that volume is in your analytics you can no longer read whether the commercial pages are doing anything at all. An excluded phrase costs you some traffic. An included one you can't act on costs you the ability to read everything else.
One caveat on my numbers: the count against each phrase is how many distinct expansions surfaced it, so it's persistence, not volume. Useful as ordering, never as a forecast.
Your accounting test is the stronger version of this, and I'd rather have your data than mine. G2 covering the category for a decade and still being absent from the top twelve on the operational questions isn't a coverage gap, it's a genre gap. Nobody writes down what actually happens on a Tuesday except the vendor whose product does it.
I am adopting the person-rule, it beats any topic rule I have tried. We landed somewhere similar by accident. Every question type we run is commercial by design and there is no what-is-X type at all. Your pollution point cuts deeper though. Once definitional volume mixes into the numbers you cannot tell whether the commercial layer moved.
We're seeing this in B2B sales too — buyers come into the first call already having an AI-generated shortlist, and if you're not on it, you're not in the evaluation. The problem is that most founders think about GEO as a marketing question. It's actually a sales pipeline question. The leads you're not getting aren't going to your competitors' sales team. They're going to ChatGPT first.
The pipeline framing is right and it has one practical consequence. The shortlist is inspectable. Your buyers' first-call list comes from questions you can ask the same five engines yourself, and read who is on it and which pages put them there. Most teams treat it as unknowable and it is one afternoon of checking. What category are you selling into? I will pull who is on the shortlist right now.
Hit the same wall from the other side. We rank fine on Google for our category term, but ChatGPT kept naming two competitors - both had the differentiator spelled out on their homepage while ours sat in a feature bullet, same as your founder. Moved it into the hero copy and we started showing up a few weeks later. The reddit-cited-9x-more-than-G2 number matches what I keep seeing too.
I would love the detail if you are open to sharing. Which engines picked you up, and how were you checking, rerunning the same question by hand or something more systematic? The few weeks lag is interesting on its own, it roughly matches how long the engines take to refresh what they read. If you tell me the category I will run it both ways and you can see exactly where you sit now versus your two competitors.
This is such a useful reframe. I've been assuming directories were the right move for any tool I help build, without checking whether the citation gap is different for B2B vs consumer categories. Going to actually run your test instead of assuming. Does the 'competitor homepage as source' pattern hold even for newer/less established products, or does it mostly show up once a competitor already has some organic authority?
Mostly the second, with a sharper edge than authority. The page has to already be in the engines' reading list . For very new products the reading list often skips owned pages entirely. We recently reran 7 small products through all our question sets and 3 of them appeared nowhere. So the sequence seems to be, get read at all, then the plain-sentence effect decides whether being read converts to being cited. The open-slot test tells you which stage you are in before you spend anything.
this tracks with something I'm noticing firsthand, though from the other direction — I've been putting most of my early effort into reddit threads instead of directories/review sites for a consumer android app, partly just because that's where genuine conversations happen, not because I was thinking about AI citation at all. good to see data backing that instinct up
makes me wonder if for early-stage consumer apps specifically, being genuinely present in reddit threads (not just linking, actually answering things) might end up doing double duty: real users now, and becoming one of the sources that gets cited later once there's enough of a footprint. curious if you've seen a threshold where that starts kicking in, like is it about post volume, upvotes, or just being in the discussion at all.
We measure which threads get cited, not what earns the citation, so I cannot give you a threshold. What the data does show reddit is 5 to 7% of everything the engines cite regardless of question shape, and they cite specific aged threads repeatedly rather than whatever is newest. The practical way to go about it, find the threads in your category that already get cited, those exist and are findable, and be genuinely useful in those rather than starting fresh ones. Your double-duty logic is sound either way, the users are real even if the citation never comes.
"find the threads that already get cited rather than starting fresh ones" is a real strategy shift from what I've been doing, I've mostly been finding today's posts and replying fresh. is there a practical way to spot which threads are already getting cited without your data, or is it mostly just the obvious signal of an old thread that's still getting upvotes/replies months later
and yeah, agreed on the double-duty logic holding either way, that's honestly the more important part. citation would be a nice compounding bonus but genuine usefulness now is the thing that has to hold up on its own regardless
There is a free way that gets you most of it. Ask your actual buyer question in Perplexity and in ChatGPT with search on, and read the citations directly, both show them. Do it for your five most important questions and you have the cited thread list for your category in twenty minutes. The threads that show up are usually exactly what you guessed, aged, still accumulating replies, title phrased like the question. Google's top results for the question with site, reddit.com are a decent preview too, since the engines lean on search plumbing to find candidates. Re-ask monthly, the list moves slower than you would think.
And agreed on your ordering. Useful now has to stand on its own, the citation is compounding interest on it.
that's a genuinely usable method, twenty minutes and no tools needed. going to actually run this for a few of my category's questions this week and see what shows up
"the citation is compounding interest on it" is a good closing line for the whole thread honestly. appreciate you walking through the practical side this thoroughly, not many people would lay out the actual method instead of just the concept
No problem. Run it and post what you find, even a boring result maps your category.
ran it. Honest result: nothing Reddit-sourced showed up prominently for my category's core question ("best AI assistant for android calendar/texts"), it's dominated by blog roundup content (Lindy, Morgen, Carly, Zapier-style "best of" posts), not aged reddit threads
which is its own useful data point I think, my category might just not have an established, citation-worthy reddit thread yet the way more mature categories do. or the roundup-blog format is simply what ranks for "best X" style queries regardless of category. either way, better to know now than assume reddit presence was quietly compounding into something it isn't yet
Posting the boring result puts you ahead of most of this thread, closing the loop in public is the rare part. Two readings. The 5 to 7 percent reddit number I gave you is an average across categories and averages contain zeros. An aged citable thread only exists where people have been arguing about the answer for years, and your category is too young to have one. Nothing to compound on yet, so you just saved yourself months of replying into threads the engines never read. And the roundups themselves are the finding. The engines handed you the exact pages that carry your question, and roundup posts get refreshed, their authors can be pitched with something concrete. Getting added to two pages that are already cited beats starting ten threads that are not. You also got your real competitive set for free. When someone asks that question, Lindy and Morgen are who you are up against, not whoever ranks in Google.
"the roundups themselves are the finding" completely reframes what I thought was a dead end. hadn't considered that getting into an already-cited roundup is a completely different, much more tractable goal than trying to manufacture a citable reddit thread from nothing
also hadn't thought about it as getting my real competitive set for free, genuinely useful to know it's Lindy and Morgen I'm being compared against in that moment, not whoever happens to rank in google that week. going to actually look into pitching those roundup authors directly now, that's a concrete next action I wouldn't have arrived at without this thread
This lines up with what I saw running the same check across roughly 30 client sites, ChatGPT by hand plus Google AI Overviews pulled through a SERP API.
The homepage point held up. Every client that got cited was one where the model quoted their own copy back at me, down to naming the specific laser device a clinic lists on its page. The ones describing themselves in category language, "advanced skin treatments", got nothing.
Your open slot test is the strongest bit. On "best hospitals for robotic knee replacement in mumbai and thane" the AI Overview named one client and skipped another who's a direct competitor on that same query, so the slot was open. On "best laser marking machine brands in India" it only listed the big manufacturers and my client had no way in. That same client is #1 and cited on a narrower query about stamper machines.
Would add one thing: ranking doesn't buy citation. My own site is #1 organic for a question ChatGPT still answers from OpenAI's docs. Went 0 for 6 on that test
Thirty sites checked by hand is a better dataset than most published studies in this space, and the verbatim-quoting detail matches what we see when we fetch the cited pages, the engines lift the sentence, not the gist. Your ranking does not by citation example has a mirror in our data. Same masthead, wildly different treatment per engine. A local publisher we measured gets cited 38 times by Perplexity and 3 times by ChatGPT in the same window, same questions. Rank position and citation are just different systems. Which categories are your 30 clients spread across? If any overlap what we track I can show you the same cut from the automated side.
Mostly Indian local services, so probably a different shape from your publisher data. Rough split of the 30:
So the overlap with what you track is probably thin, maybe the two industrial B2B ones and my own site.
That 38 versus 3 split is exactly the hole in my data. I only tested ChatGPT and Google AI Overviews, so I genuinely don't know whether the clients ChatGPT ignored are quietly getting picked up by Perplexity instead. Worth noting my numbers are single snapshots too, not citation counts over a window. I watched one site move from #3 to #8 on two API calls minutes apart, so I don't lean too hard on any individual row.
Send me the questions you use for the two laser marking clients and I will run them through all five engines and post what comes back. That covers your Perplexity blind spot for one vertical at least. Your snapshot caveat is the right instinct too. Every share we track swings a few points day to day, which is why we only publish pooled windows.
Deal. Here's the set, split deliberately so your run comes back as a diff rather than another fresh snapshot.
Already lost on both engines I tested:
Already won, but only narrowly: best stamp making machine in India. That client is #1 organic and does get cited by ChatGPT on it, so it's the one row where I know the ceiling exists.
Untested middle ground, which is where I actually expect the interesting result:
The same pattern shows up in our referral data: AI-referred visitors arrive already convinced by one specific claim, so the page that states the category in a customer’s own words wins the citation. Review listings get you mentioned; the homepage gets you cited. We build AI-native analytics (https://amami.dev) and this homepage-language effect is exactly what we see in the numbers.
The same pattern shows up in our referral data: AI-referred visitors arrive already convinced by one specific claim, so the page that states the category in a customer’s own words wins the citation. Review listings get you mentioned; the homepage gets you cited. We build AI-native analytics (https://amami.dev) and this homepage-language effect is exactly what we see in the numbers.
This matches exactly what I've seen in the edtech/course creator space.
When I built iLoquio (a course platform), I noticed that when people ask AI "what's a Teachable alternative", they almost always get cited back to Teachable's own comparison pages, or to a competitor's homepage that literally says "the alternative to Teachable with no monthly fee."
The review sites (G2, Capterra) barely show up for those queries. What shows up is whoever was clearest on their differentiator, on their own homepage, early.
Your framing of "the gatekeeper was her own homepage" is exactly right. The implication for any founder building in a competitive category: if you're not using the exact language customers use when searching, you're invisible — not just to Google, but now to AI inference as well.
The lesson I took: before worrying about G2 listings, make sure your homepage says what you do in the clearest terms a customer would use to describe you to a friend.
The Teachable pattern shows up in our data as a constant rather than an edtech quirk. We split citations by question shape and competitor-owned pages are roughly half of what the engines read for every shape: 50.7% on best-of questions, 49.1% on alternatives, 46.2% on narrow problem-solving ones, across 186k citations in 28 days. So whoever states the differentiator plainly on their own page is competing for half the reading list before any review site enters. Your no fee example is that mechanism in one sentence. Did it work in reverse for iloquio, did your own citations move after you made the homepage say it plainly?
The useful reframe is that the citation went to whoever stated the category in the same words a person would type. A feature bullet does not do that; a page whose heading is literally "no bank linking required" does. The tactic I would hand her is to list the ten questions she wants to win, then confirm each one has a page answering that exact question in that exact phrasing, because right now a competitor is getting paid for her positioning.
The ten questions list is how I would run it too, with one caution from this same thread (See alexecho1 comment) built 18 pages for exactly this and got zero citations, so the page existing is not the bar. Before writing anything I would put the ten questions through the engines and note who wins each one today. Some will be locked to household names and not worth chasing. The exact phrasing pages go on the winnable ones, and then you ask the same ten questions a month later to see what moved.
The B2C vs B2B directory split is the one I got wrong first. My assumption was the same — get listed on the right sites, citations follow. That's a B2B playbook and it doesn't port to consumer.
The "plain sentence on the homepage" finding matches what I saw when I diagnosed my own sites. I ran an automated content pipeline for two weeks —18 GEO-optimized articles, technically correct, proper markup, sensible internal links. Zero AI citations. When I finally looked at who was getting cited for my category query, it was a competitor's homepage — one clear sentence stating the specific capability as the lede, not buried in a feature list.
The query class split is worth isolating too. I've been tracking the same URLs across a narrow-intent query ("tool that does X specific thing") vs. a broad-category query ("best tools for Y"). Narrow queries cite whoever states the capability most directly — that's a homepage rewrite problem. Broad ones are messier: Reddit threads, YouTube, sometimes nobody recognizable. Different gatekeepers, different work.
Your test — look at who's already getting named — is the right start. If it's apps you've never heard of, the slot is open. If it's all household names, the citation behavior is already locked to brand signals and homepage rewrites probably won't move it.
We label every prompt by question type before we ask it, so I could run your narrow-versus-broad split this morning. Across 28 days, broad category questions pull 5.2% of their citations from reddit or youtube and narrow problem-solving ones pull 6.9%. Review sites invert it, 1.3% broad against 0.5% narrow. The mixes do differ, just not the way I expected from your description, and it is an average across 295 categories so it cannot see which page wins inside any one of them.
On the pipeline result, the closest thing I have from our side is that 46.4% of the pages the engines cite are owned by a vendor competing in that same race. Consistent with the citation not coming from volume around the category.
Your household-names line is sharper than the test I wrote. Where do you actually draw it, recognition alone, or is there a point where you stop bothering with the rewrite?
The B2B/B2C split might be the wrong cut of that data. The query you ran was her differentiator - works without linking a bank - which is product-shaped, so product pages get cited. Your own aggregate says reddit gets cited nine times more than G2 across the categories you track. That is what a category query pulls: best budgeting app.
Same product, two query classes, two different source mixes. She needs the plain sentence on her homepage for the narrow one and presence in threads for the broad one.
Worth running her category query before she rewrites anything. If those three cited pages flip to reddit and youtube, the variable is query shape.
That is a better cut than mine and I should have separated the two, so I went and measured it. Our prompts carry an intent label already, so I split the last 28 days of runs into broad category questions and narrow problem-solving ones and counted only citations that appeared inline in an answer. Broad questions: 5.2% of citations from reddit or youtube, 1.3% from review sites. Narrow questions: 6.9% reddit or youtube, 0.5% review sites. So no flip toward reddit on the broad ones, if anything slightly more community content on the narrow ones. The review-site half of your intuition does hold, broad questions pull about 2.6 times the review-site share.
This is an average across about 295 categories, so I cannot see which specific page wins inside any one of them. On your feedback, I added a consumer budgeting category with both question shapes in the same prompt set, including the exact narrow one from the post. And I shipped the split itself,share by question type instead of blended. First category we ran, one product holds 95% on the broad question and 40% on the narrow one. First budgeting runs land tomorrow on the next daily batch. I'll keep you posted on the results.
The reddit half of that was wrong then, and 295 categories beats my guess.
The more useful number is in your own reply: 95% on the broad question and 40% on the narrow one, same product. The source mix barely moved between question shapes, but which product gets named moved by more than half. Broad and narrow are not different channels, they are different competitive sets, and she is losing one she has probably never checked.
Worth logging which pages get cited on that 40% question, not only the share. If those turn out to be competitor homepages as well, homepage phrasing carries both shapes and the directory listing was never the lever.
Closing the loop on this. The different-competitive-sets frame you landed here ended up built into the product, every question is now labeled broad or narrow and measured separately. I put up an offer post where I run any category both ways and post the result in the thread, and the first seeded run is in its comments. If you want one for a category you care about, name it there: https://www.indiehackers.com/post/you-told-me-narrow-and-broad-questions-have-different-gatekeepers-name-your-category-and-ill-run-it-both-ways-63413ba42a
Ran your test on the 40% question set this morning. Top of the reading list for the narrow accounting questions irs.gov and quickbooks.intuit.com at 8 citations each, then reddit and pcmag at 7, xero.com at 6, with pilot.com, bench.co and rippling.com behind them. G2 and Capterra are not in the top twelve at all, in a category they have covered for a decade. So the pages carrying the narrow questions are competitor product pages plus the IRS, and the review layer never enters. That is data to your conclusion. The phrasing carries both shapes and the listing was never the lever for either. The competitive sets framing is great.
The homepage-as-gatekeeper finding matches what we've seen — engines cite pages that say the claim plainly enough to quote. Her competitor's 'no bank linking required' line is exactly the kind of copy that gets lifted verbatim. We hit the same wall auditing AI citations for our analytics product (https://amami.dev): the pages that get cited are written as answers, not feature lists. Worth rewriting your homepage around the one sentence you want quoted.
Written as answers rather than feature lists matches what I see. What I would add is that it has to be close to the words a buyer would actually type. Her competitor's line reads almost exactly like the query, which is probably why it gets lifted whole. What did your audit turn up on your own domain, did the cited pages skew to your docs or to third parties?
This is a good example of how AI citation behavior doesn't map cleanly onto traditional SEO rankings. Was it purely about content depth on the competitors' homepages, or did you notice structural things too, like how the info was organized or phrased, that seemed to make AI more likely to pull from them?
Phrasing more than depth. The competitor pages that got cited were not longer or more thorough than hers, and a couple were thinner. They stated the constraint in one plain sentence near the top. She had the same fact, as a feature bullet halfway down. I cannot see inside the ranking, so that is a pattern across the pages that got cited rather than a mechanism I can prove.
The shift from the original assumption to what the actual report showed is interesting. Curious how often the cited sources differ from what you would expect going in.
Often enough that I stopped guessing first. I have a restaurant in Miami so I ran, best pancakes in Miami, 3 of the 6 restaurants the engines recommend sit on a single listicle published in 2020, which turned up in 4 separate runs. I would have bet on recent reviews or maps.
That’s a useful example. The fact that one old listicle keeps appearing across separate runs is probably more important than the individual result. If you’re open to continuing the conversation, what’s the best email to reach you at?
Feel free to reach me at hello @ orbator.io
Thanks! I’ve just sent it over.
Looking forward to hearing your thoughts whenever you have a chance.
This is measurement system lag in action. Founders built their intuition when review sites = distribution. That measurement system told them "get on the review sites" because that's what worked. But the distribution channel shifted (AI is now the amplifier) and their measurement system didn't update. Classic founder blindspot: you can't see the problem your measurement system can't measure. Until you can't compete.
The lag is nastier than just missing data, because the old number still goes up. Listings get added, the directory dashboard looks healthy, and the answer names someone else the whole time. Nothing feels broken, which is why it runs so long before anyone checks.