2
9 Comments

Our own AI-visibility score started at 0/100. What 2,150 cited URLs taught us about getting recommended by ChatGPT

Hi IH — I'm Anil, solo and bootstrapped, building Promvia: it checks whether ChatGPT, Perplexity, Gemini and Google's AI answers actually name your product when buyers ask for a recommendation, and what those answers send your site. Launched August 2026, €0 MRR so far, building in public. Disclosure up front: the numbers below come from our own tracking.

The thing worth sharing is a finding, not a feature. We track a fixed set of buyer prompts every week across six answer engines and log every URL the answers cite — about 2,150 cited URLs over 14 days in one niche (software tools). Two things fell out:

  1. "Alternatives to X" prompts cite comparison-shaped pages (paths like /vs, /alternatives, /compare — vendor pages and blogs included, not just G2 or Capterra) in 34–43% of citations. "Best X" prompts: 2.8%.

  2. When we first counted by directory DOMAIN instead of page shape, the effect looked ~10x smaller. The domain list was a bad proxy. What gets cited is the page type, wherever it lives.

The practical version: a well-structured /alternatives or /vs page on your own domain competes for the same answer slot as a G2 grid. "Get listed on directories" and "build comparison pages" are sold as two tactics; at the citation level they look like one. And the cited pages had almost no organic traffic — winning the SERP and being chosen for an answer are different games.

Caveats, honestly: one niche, two weeks, URL-path labeling rather than rendered pages. Direction solid, magnitudes indicative. We pre-registered a follow-up (vendor-authored vs third-party comparison pages) and will publish it on Sep 7 whatever it says.

We eat our own cooking: Promvia's own domain scored 0 on day one, and we publish our own weekly run live at promvia.app/live so the score is a public number rather than a promise.

Question for people running product sites here: do your /vs or /alternatives pages pull AI citations (or AI referral traffic) out of proportion to their organic traffic? That publisher-side number is the one nobody seems to have.
posted toAvatar for product Promvia
Promvia
  1. 1
    Your line that the cited pages had almost no organic traffic matches what I found on my own site, and the size of it surprised me. Over 92 days, the page with the most ordinary Google search impressions (1,479) earned zero Copilot citations. A page with 78 impressions earned 63 citations, more than half the site's total. Bing and Google also cited near-opposite pages: my top Bing page had 11 Google AI impressions, Google's top page had zero Bing citations. Rank and citation were not just different games; they were close to inverted. One caveat on "the citations are weekly and reproducible". A 2026 study across four engines found only 34% to 42% of cited sources come back when the same question is repeated, even within a day. Your 92% single-appearance tail is probably mostly that churn, and the 21 repeat domains are the real signal. It fits the wider data too: across 25 million cited links, 84% pointed to earned media, and brand-owned sites came out at roughly 3% to 10%. On the publisher-side number nobody has: for two engines it exists. Bing Webmaster Tools' AI Performance report logs Copilot citations per page with the queries behind them, and Search Console's generative AI report logs impressions by page and country. Neither covers ChatGPT, but both are records rather than samples, and they are what let me check my own pages. I do not run /vs pages, so I cannot answer your question directly; my numbers, zeroes included, are here: https://www.dhawalshah.net/article/ai-visibility-tracking/
  2. 1
    The distinction between being cited and being recommended is huge; the latter depends on whether the page gives the model enough context to match a real buyer’s situation. I’d segment the 2,150 citations by prompt intent and compare the pages that earned repeated mentions, not just total citation count. That should reveal which claims and proof points are doing the actual work.
    1. 1
      Agreed on the distinction, and we do split it — cited, mentioned and not-cited are three states in the product rather than one. But your second suggestion is the more interesting one, and I went and ran it, because I had not looked at the panel that way. Segmenting by repeated mentions instead of total volume, this week's run across the 40 buyer questions: 790 distinct domains cited. 727 of them, 92%, appear in exactly one question. Only 21 appear in three or more. That repeat set is almost entirely platforms and publishers, not vendor pages: YouTube in 30 of the 40 questions, Reddit 28, TechRadar 10, Forbes 7, CNBC 6, PCMag 5. So your method surfaces something real, and it points somewhere I did not expect. The pages that earn repeated mentions are not the ones making claims about a product; they are the substrate the engines keep returning to. Vendor pages live almost entirely in that 92% tail, chosen once for one question and then not again. Which suggests the claims-and-proof-points work, where it happens, happens per question rather than accumulating into a durable position. Two things I should be straight about rather than dress up. Counting was already deduped: a domain counts once per question per engine, so four engines naming one page on one question is four, never four for one page. Volume was never raw volume. But that is exactly why your reframing earns its keep. Breadth across questions and breadth across engines are different axes, and I had been reading the first as if it implied the second. The part this instrument cannot answer is which claims and proof points do the work. We store cited URLs, not rendered page content, so I can tell you a page was chosen and for which question shape, not what about it was persuasive. That needs a content analysis on top, and I would rather name the gap than infer it from URLs. On cited versus recommended, the sharpest version I have is our own domain: on branded questions we are named 4 times out of 4; on the 15 where we compete on merit, zero. Same product, same pages. Being retrievable and being chosen really are two different measurements.
      1. 1
        This is the useful cut. 92% one-question domains versus a tiny repeat set of substrate publishers is a much cleaner story than raw citation volume. Two takeaways I am stealing: 1. Breadth across questions ≠ breadth across engines. Your dedupe already forced that apart. 2. Vendor pages living in the one-shot tail means “claims and proof” mostly buys a single retrieval event, not a durable slot. Your branded 4/4 versus merit 0/15 makes the same point from the other side: retrievable and chosen are different jobs. Respect for naming the instrument gap too. URL-level citation can show *that* a page was picked and for which question shape; it cannot show *which* claim or proof point did the work. That content pass on top is the next measurement, not something the URL log can pretend to answer. If you ever publish the question-shape breakdown for those 21 repeat domains, that would be gold for people trying to stop optimizing the 92% tail.
  3. 1
    The 2,150 cited URLs make the finding much more interesting than another AI-visibility claim. Have you seen /vs or /alternatives pages produce meaningful qualified traffic from AI answers yet, or is citation volume still the stronger signal?
    1. 1
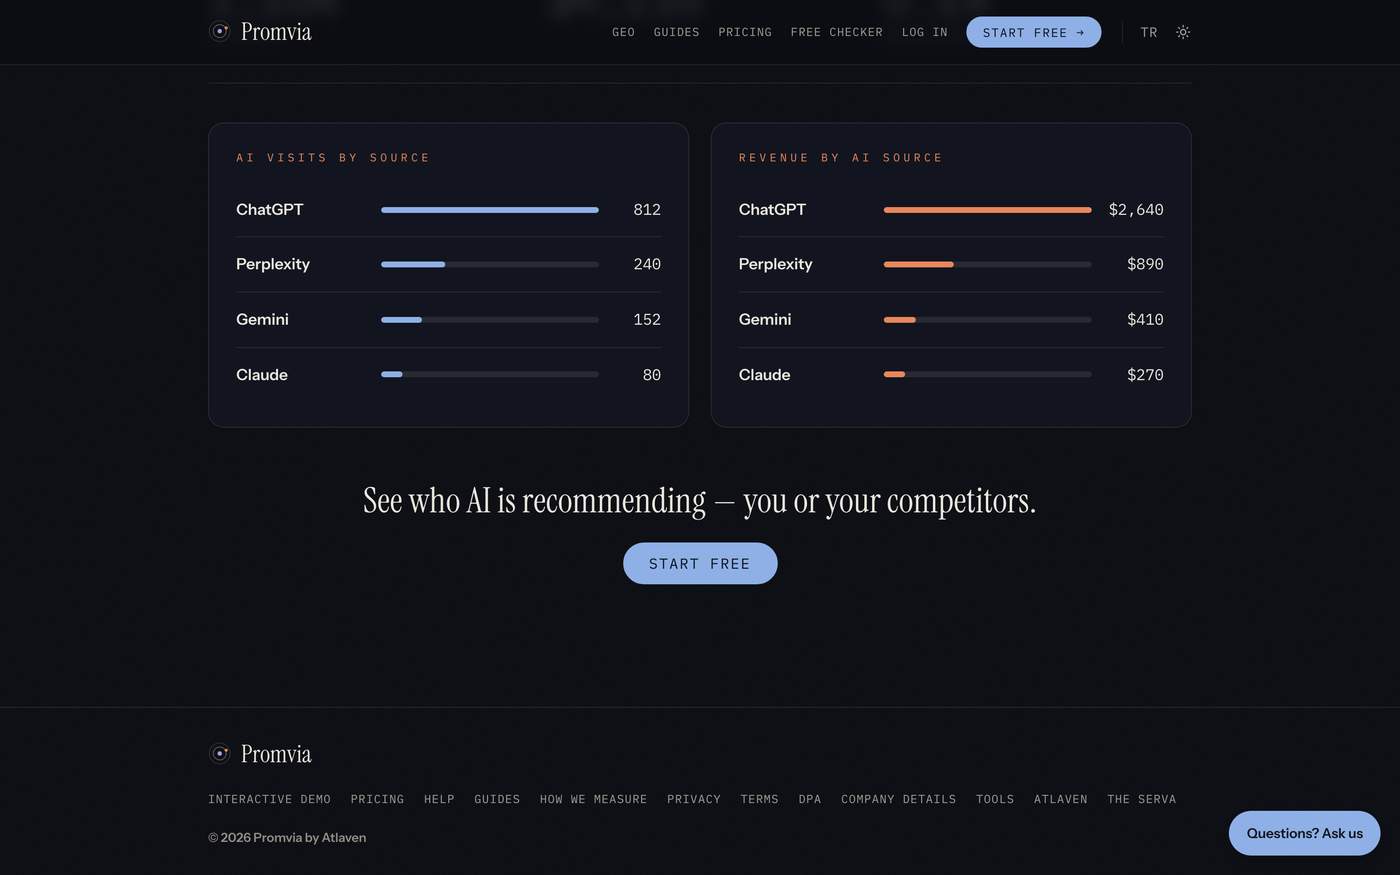
      Honest answer: citation volume is the stronger signal for us so far, and I would not claim qualified traffic yet. Two reasons, both measurement rather than marketing. 1. Most assistants open links with no referrer, so the visit lands in analytics as Direct. We keep two buckets apart: confirmed (a referrer, or an assistant user-agent like ChatGPT-User fetching the page on a user's behalf) and inferred (Direct sessions landing cold on a deep /vs or /alternatives URL, which typed-in Direct almost never does). The inferred bucket runs roughly 2 to 3x the confirmed one. That gap is the honest size of the attribution hole. 2. On our own domain the numbers are small enough to say out loud: a handful of AI-referred visits and no attributed revenue. The comparison pages that got cited in the dataset were third-party ones, and we do not have their analytics, which is exactly the publisher-side number I was asking for. What I can say: the citations are weekly and reproducible, the traffic is not yet. We started publishing the source side in the open today (promvia.app/ai-source-index, 40 fixed buyer questions across seven engines every Monday), and the first week already showed the engines leaning on YouTube and Reddit far more than on any directory for consumer questions. If your /vs pages show AI referrals out of proportion to organic, I would genuinely like to see the numbers.
      1. 1
        That attribution gap is the interesting part, especially the confirmed vs. inferred split. I’d be interested in comparing notes on what the /vs pages are actually driving. What’s the best email to reach you on?
        1. 1
          Happy to compare notes: support@promvia.app reaches me directly. If you send the /vs URLs you are looking at, I can run them through the same weekly panel and share what the engines cite for their questions, no strings.
          1. 1

            Thanks! I’ve just sent it over.

            Looking forward to hearing your thoughts whenever you have a chance.