Why I shipped the main feature [Multimodel evaluation] on v3. Learnings from 1 month and 62 user signups
if you are here, please upvote the v3 launch, means alot:
https://www.uneed.best/tool/promptperf
1 month, 62 signups, and a lot of clarity
From day one, I wanted to build a tool that will:
Evaluate prompts across GPT-4, Claude, Gemini…”
But I held off.
I shipped this workflow after 3 weeks of waitlist landing page:
-> Enter your API Key, Download the template, create your test cases, Upload your test cases, Evaluate across 1 model.
Instead of building the most complex feature first, I focused on removing friction.
And that made all the difference.
🔹 v1: CSV upload + your own API key — functional, but high drop-off
🔹 v2: Removed the API key requirement — friction dropped instantly
🔹 v2.5: Added test case templates, onboarding flows, and an in-browser editor — users started evaluating within minutes
These small, fast iterations taught me more than any roadmap could:
→ The real blocker wasn’t lack of features, it was setup fatigue
→ Users needed momentum before they needed depth
After all this small iterations I saw 8 in 10 new signups were atleast running 1-2 evaluations (big win for win for me as the user is now actually completing the whole app flow)
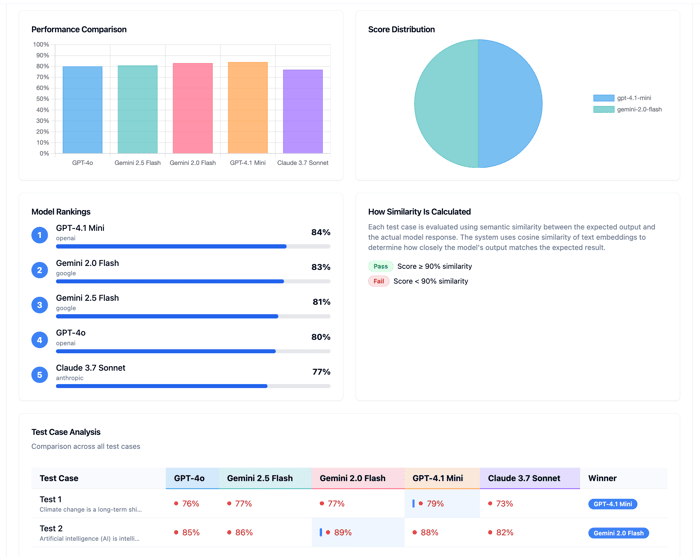
Only then did I ship Multimodel Evaluation in v3:
✅ Rebuilt dashboard to compare models side-by-side
✅ Redesigned exports to handle multiple outputs cleanly
Lesson:
Sometimes, delaying the “hero feature” lets you uncover what users truly need first.
And once the friction’s gone, your biggest feature finally gets used.
Still building. Still learning.
