100K+ Events Monitored: What Breaks in Production and Why Small Teams and Solo Founders Are the Last to Know
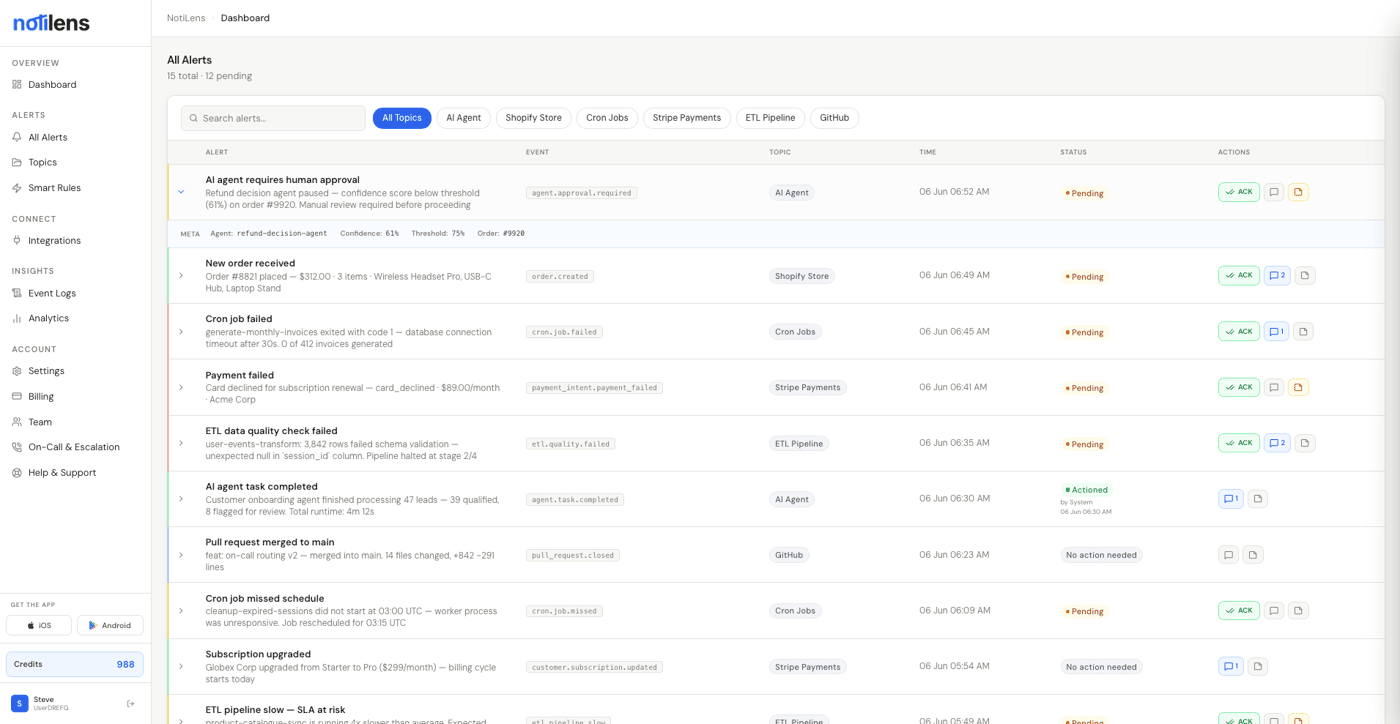
We built NotiLens originally for our own product - CollabZap. Small team, no DevOps, no one watching dashboards. We were flying blind and didn't know it until a customer told us something was broken.
That pain turned into a product other teams started using. After processing 100K+ business events across all products monitored on NotiLens, we have data on what actually breaks in production for small teams.
2,000+ problems caught. Here's the breakdown:
1. Silent failures - 40%
No error. No crash. Just stopped working. Payment not captured. User not activated. Server looked completely fine.
Logs are clean. Uptime monitor is green. But somewhere in the middle, a process quietly died.
2. Cron jobs that quietly died - 25%
Job stopped running at 3am. Nobody knew. Customer noticed their report hadn't updated in 2 days. Job had been running - just processing 0 records.
Scheduled jobs are invisible by default. They either run or they don't, and most setups have no way of knowing which.
3. AI agent flows that silently broke - 20%
Agent triggered. Tool called. Response never came back. No exception, no timeout. Just stuck mid-flow - task never completed, nobody knew.
As more products wire AI agents into core workflows, this one is going to get worse.
4. Metric drift - 15%
Not a crash. Just a slow bleed. Processing time creeping up a little each day. Nobody noticed until it was 3x slower than last week.
Drift looks like normal variance day to day. You need a baseline to know when something has genuinely shifted.
## What Solo Founders and Small Teams Miss
"Server is up" is not the same as "product is working."
Your uptime monitor checks one thing. Everything that happens after jobs running, flows completing, events processing, metrics staying stable is invisible to it.
Worth setting up early:
- Heartbeat on every cron job - if it doesn't check in on schedule, something's wrong. Don't wait for a customer to notice.
- Confirm events end to end - don't just log that something arrived, confirm it was actually processed.
- Baseline your key metrics - know what normal looks like so drift is visible before it becomes a problem.
- Alert on silence - if a flow that runs 50 times a day suddenly runs 0, that's a signal. Silence is data.
Most of these cost nothing to set up. The cost is not having them when something quietly breaks at 2am.
What breaks in your production that you only find out about later?

