I built a PDF → Excel tool. Now I'm trying to find the first 30 people who actually need it.
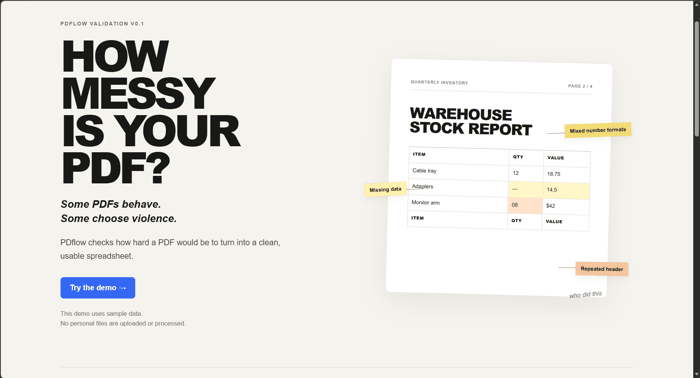
I built PDflow for messy PDF → Excel workflows.
Now I’m looking for the first 30 people who actually need it — especially anyone with ugly PDFs that still require manual cleanup.
If that’s you, I’d love your feedback.

For the first 30, I’d narrow the promise to one ugly document family rather than “messy PDFs” broadly—e.g. one recurring report format with a known cleanup step. Ask each tester for the original PDF, the corrected spreadsheet, and the one field they check first; that gives you a measurable before/after and a sharper landing-page promise. I’d also log failures by layout pattern, not just “conversion failed,” so the next fixes improve a whole cluster of documents.
This is a really useful framing.
I’ve been thinking about “messy PDFs” too broadly, and I agree that the first 30 probably need to come from one repeatable document family rather than random edge cases.
The idea of collecting the original PDF + corrected spreadsheet + the first field the user checks is especially interesting. That would give me a much better usability benchmark than just “did export succeed?”
I’m already logging failures by structure/layout pattern internally, so narrowing the external beta around one recurring workflow feels like the logical next step.
I’m now trying to decide which document family has the strongest combination of frequency, cleanup pain, and willingness to pay.
If you were choosing the first wedge, would you optimize for the most common document type, or the one with the highest manual cleanup cost?