I ran OpenAI's new cheap model against Claude for a week. Here's what happened to my bill.
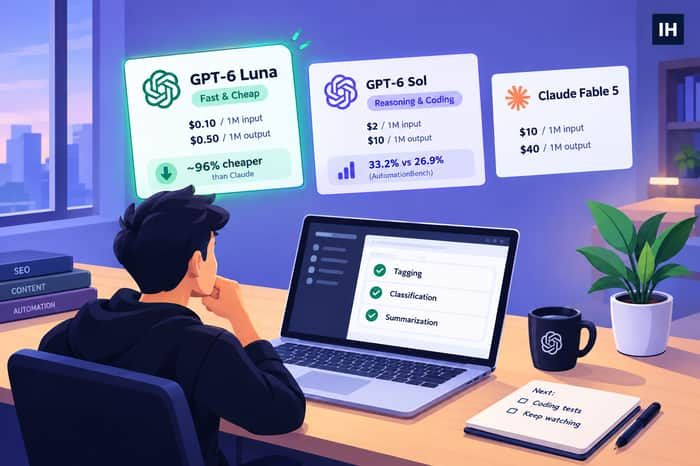
OpenAI shipped two new models this week, GPT-6 Sol and GPT-6 Luna. Sol's the reasoning/coding one, Luna's built to be cheap and fast. I run most of my content and SEO pipeline through API calls, so a new model launch isn't news to me until I know what it does to my invoice. I spent this week finding out.
The number that actually made me stop scrolling
Luna costs $0.10 per million input tokens and $0.50 per million output. OpenAI's own comparison puts that at roughly 96% cheaper than Claude Fable 5 on a per-task basis. Sol, the bigger sibling, runs $2/$10 per million short-context, and supposedly beats Claude Opus 5 on OpenAI's AutomationBench eval (33.2% vs 26.9%) for about 9% of what Opus 5 costs per task.
I don't trust a benchmark a company runs on its own model. But I do trust my own bill, so I ran the cheap one for a week on real work instead of arguing about the PDF.
What I actually tested
Not the flashy agentic stuff, the boring high-volume layer of my stack: metadata tagging, first-pass content classification, quick summarization passes I currently run through a budget model anyway. Swapped that layer to Luna for a week, kept everything else untouched.
Output quality held up fine for that tier of task. Nothing embarrassing, nothing I had to rerun. Given the price gap, that's an easy swap for me going forward, at least for that layer. I'm not touching my actual drafting or strategy work with it.
Where I'm not buying the hype
Sol lost to Claude Fable 5 on DeepSWE 1.1, a coding benchmark, 68.8% to 69.9%. Small margin, but it's still a loss on exactly the task type a "built for complex coding" model should win. If you're vibe-coding an MVP or your product is dev tooling, that one line in the benchmark table matters more than the AutomationBench headline. I'm leaving my coding assistant alone until someone outside OpenAI reproduces that number.
Where things stand for me
Cheap tier, tested and swapped for the low-stakes calls. Reasoning tier, watching and not touching. That's the whole decision, and it took a week of actually running the thing instead of reading about it.
If anyone else has run Sol on real coding tasks, not the benchmark suite, I'd genuinely want to compare notes. That's the gap in this launch nobody's filled yet.

This is the right split: route by failure cost, not model prestige. I’d add a small holdout set of real jobs and track rework minutes, not just pass or fail quality; a cheap model wins only if downstream cleanup stays flat. Also cap retries, since hidden reruns can erase the invoice savings.
This is exactly why I’ve been thinking more about measuring AI outputs in the wild rather than relying on model benchmarks.
I’m building a small stateless AI visibility platform around a related problem: you enter a brand and its competitors, the tool generates prompts to run against AI models, then you paste the actual responses back in. It analyzes whether the brands are being mentioned and how they compare across the responses.
What I find interesting is that the “best” model on a benchmark isn’t necessarily the one that gives you the most useful answer for a specific category or use case. The actual outputs can tell a very different story.
Your approach of running Luna on your real pipeline for a week is pretty much the same philosophy I’m taking with AI visibility — test the actual outputs, not just the headline benchmark numbers.
Would be interesting to see someone run the same prompts across Sol, Claude and Gemini specifically for brand/product recommendation queries and compare what brands each model surfaces.
I like that you kept drafting on the cheap tier. A batch may look fine until one bad response corrupts a downstream export. I'd check the response format at every boundary and save failed records with their original input. Then retry only those failures on the stronger route. That keeps the retry bill low and makes debugging much easier.
That’s a really good point about checking the output at every boundary. I think the same principle applies when you’re evaluating AI responses for things beyond a single pipeline.
I’m actually building a small AI visibility platform around this idea — users run the same prompts across AI tools, paste the real responses back, and the platform analyzes whether their brand and competitors are being surfaced.
The more I work on it, the more I realize that the raw response is only the starting point. The interesting part is consistently structuring and comparing those responses without losing the original context.
We swapped that same layer — metadata tagging and first-pass classification — and it held up fine. What broke wasn't quality: it was the long tail where the cheap model has to return a strict schema across hundreds of calls, and one malformed field quietly poisons the batch. Validating every response and re-running only the failures on the expensive tier still costs a fraction of routing everything there. On coding, same as you: not swapping until someone outside the vendor reproduces that benchmark.
The long-tail failure point is really interesting. It’s easy to look at the average output and conclude a model is good enough, but the edge cases are often what matter once you’re running hundreds of calls.
I’m working on a related problem with AI visibility — I built a stateless platform where you run prompts across AI tools and paste the actual responses back for analysis of brand vs competitor visibility.
One thing I’m learning from that is that consistency across a set of responses can be more useful than judging any single response. A model mentioning your brand once doesn't tell you much; seeing the same pattern across dozens of prompts starts to become a much more meaningful signal.
The validation + selective retry approach you described is a pretty interesting way of handling that same “don't let one bad output ruin the dataset” problem.
Your split (swap the boring tier, leave drafting alone) is the sane way to read a launch. If you're testing the cheap layer anyway, two more worth one week each: Muse Spark through Meta's Model API, whose Contributor pricing is very low if you accept your prompts being used for training (fine for metadata tags, not client data), and Glimmer, Meta's open model, which runs locally so classification costs nothing per call. The benchmarks & research section of shipwithmuse.live has community head-to-heads, including Spark 1.3 vs GPT-6. (I help curate it)
The “I trust my own bill” part is the most useful takeaway here. Benchmarks are interesting, but testing a cheaper model on real production workloads is what actually matters.
I’d be curious to see the final cost difference after a full month, especially once retries and edge cases are included.
100% agree. The real-world output is ultimately more interesting than the benchmark headline.
I’m experimenting with a similar approach with the AI visibility platform I’m building. Rather than assuming a model is good at surfacing a brand, I have users run the same prompts through AI tools and paste the actual responses back in, so we can measure what’s actually being surfaced for their brand vs competitors.
I’m finding that repeated real-world responses reveal patterns that you wouldn’t necessarily see from a single benchmark score.
I’d definitely be interested in seeing her numbers after a full month too — especially how much the retries and edge cases eat into that initial cost advantage.
This is great work — reminds me of some of the calls I've had to make building Xstream4K. What would you do differently if you started over?
The layer you swapped is the interesting one, because it is also the layer where the per-token meter can go to zero entirely.
Metadata tagging, first-pass classification, short summarization passes. Those are short-prompt, single-instruction, low-stakes calls, and that is exactly the profile where a quantized local model holds up best. Quantization degradation is real but it is concentrated in four places: long context, code, prompts carrying six constraints at once, and languages other than English. Your tagging layer hits none of those. Your decision to leave drafting and coding on a frontier model is right for the same reason, just read backwards.
Rough sizing if you ever want to price it against Luna's $0.10 per million: a 4B class model at four bits is about 2.5GB on disk and runs on a laptop with no discrete GPU. A 7B to 9B lands around 4.5 to 6.6GB. The arithmetic is parameter count in billions times roughly 0.7 for the weights in gigabytes, and context memory is charged on top of that, which is the part that catches people out on the first run.
The honest trade, since you clearly prefer measured numbers to launch PDFs: you stop paying dollars and start paying in RAM, setup time and throughput. A laptop will not match an API on batch concurrency. So the real comparison for a high-volume pipeline is your monthly invoice for that one layer against an afternoon of setup and then nothing, and whether your volume is steady enough to make that obvious.
One trap worth knowing before you benchmark: a model listed with a cloud tag in Ollama is not local, the prompt goes to the vendor's servers, which quietly defeats the point.
noizz.io/local-ai carries setup guides per model and runtime with the real download size, context window and memory cost for each, and it ranks them by licence and publisher rather than by vibes, which matters if client content is going through them. Its sizes were last rechecked against the official Ollama library on 8th August 2026, so verify anything time sensitive yourself.
The “stop paying dollars and start paying in RAM” framing is a great way to think about it. At high enough volume, the economics get pretty interesting, especially when the workload is predictable and low-stakes.
I’m working on a related problem from the AI visibility side. I built a stateless platform where you enter a brand and its competitors, run generated prompts through AI models, then paste the actual responses back for analysis.
What I’m finding interesting is that the model choice itself can change what brands get surfaced in different queries. So beyond cost and output quality, there’s potentially another dimension: how consistently different models surface the same brands across a set of prompts.
It makes me wonder whether local models could eventually be useful not just for production workloads, but also for running large-scale AI visibility experiments cheaply.
The two-tier approach is the practical takeaway here. Metadata tagging, classification, and first-pass summarisation are exactly the tasks where a 96% cost reduction matters and quality tolerance is high enough to absorb it. Swapping those and leaving your drafting and strategy calls alone is the right split.
We run a similar tiered model setup at UtilitySEO for auto-translating our site into seven languages. The translation engine runs through a cheaper model for the high-volume page-level passes, and we only escalate to a more capable model when the output needs nuance — marketing copy, CTAs, anything where a mistranslation changes meaning rather than just sounding slightly off. The cost difference at volume is significant enough that running everything through the premium tier would make the multilingual feature uneconomical.
"I don't trust a benchmark a company runs on its own model" is the most useful line in this post. The Sol vs Fable coding number is the one that should concern anyone building dev tooling, because a loss on exactly the task the model was marketed for is a specific, falsifiable claim that didn't hold up. Curious whether the summarisation quality holds when the input length pushes past the short-context window — that is where cheap models usually start dropping information quietly.
The tiered approach makes a lot of sense, especially when the expensive model is only needed for the cases where nuance actually matters.
The multilingual example is a good one because it also highlights something I’ve been thinking about with AI visibility. Different models can produce noticeably different answers to the same query, so the question isn't only “which model is cheaper/better?” but also “what does each model actually surface?”
I’m building a small stateless AI visibility platform around that. You enter a brand and its competitors, get a set of prompts to run through AI models, then paste the responses back in and the platform analyzes which brands are being surfaced.
The short-context point you mentioned is particularly interesting. I think the same kind of testing could be useful for AI visibility too — running identical prompts across models and looking at how consistently they mention/recommend different brands.
Your UtilitySEO translation workflow is a really good example of where model routing can actually have a measurable business impact rather than just being an interesting benchmark exercise.
After adding the new US-oriented layouts, what user behavior would tell you the localization fix actually improved the English funnel—template selection, completed exports, or something further downstream?