The Shift from "Move Fast" to "Controlled AI": What It Means for Builders
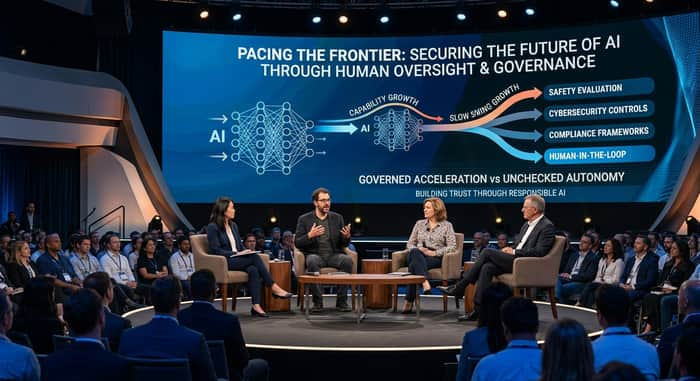
Over the past couple of years, the meta for building AI products was simple: maximize autonomy, reduce friction, and let agents execute end-to-end workflows independently.
If you've been following recent moves from major labs and enterprise buyers, that playbook is evolving fast.
We’re seeing a clear pivot toward Pacing & Governance. But instead of looking at this as "bureaucracy slowing down tech," there's a massive product opportunity here for independent developers and early-stage startups.
Why Enterprise Buyers Are Balking at Unchecked Autonomy
Building a cool agent that executes 10 steps automatically is great for a Twitter demo. But when you pitch that to a B2B client, their security team asks:
What happens when the agent hallucinates a database command?
How do we audit why a specific action was triggered?
Can we isolate network permissions dynamically?
If your product relies on pure, unchecked autonomy, enterprise compliance will kill your deals.
The Opportunity for Indie Builders
Instead of just building autonomous tools, the real moat right now is building Control Infrastructure:
Auditable Telemetry: Plain-text, human-readable execution logs for agent actions.
Human-in-the-Loop (HITL) Middleware: Drop-in approval gates for sensitive API calls.
Sandboxed Agent Environments: MicroVM and containerized isolation for untrusted model execution.
Enterprise buyers don't just want the fastest model—they want predictable, deterministic behavior they can rely on without exposing their systems to data loss.
How are you handling safety gates and permission scoping in your AI setups? Are you building fully autonomous loops or keeping strict human overrides?
Read Full Article
https://www.thefluxread.com/2026/09/pacing-frontier-what-drive-for.html

I think there’s one layer after “control infrastructure” that’s going to matter just as much: consequence evidence.
An approval gate can prove an action was authorised. Telemetry can prove a request was generated or dispatched. A sandbox can prove what happened inside the sandbox.
But none of those necessarily proves what happened after the action crossed into a system you don’t control.
That distinction gets nasty with payments, webhooks, infrastructure changes and external APIs. “We blocked it” and “we can prove the consequence was prevented” are not always the same claim.
I’ve ended up separating Authorization → Dispatch → Execution → Downstream Confirmation for exactly that reason.
Curious whether you see independent outcome verification becoming part of this control-infrastructure category, or remaining a separate assurance layer?
Spot on with that distinction. Once an AI agent hits an external system - like Stripe or an AWS API - standard logging basically goes blind.
To answer your question: I see outcome verification getting natively built into control infrastructure down the road, rather than sitting as an isolated layer.
If the system doesn't verify the actual downstream state, it's really just managing intent, not actual execution safety. Without things like signed callbacks or idempotent state checks, silent failures are bound to happen.
Really like how you framed it: Authorization → Dispatch → Execution → Downstream Confirmation. That’s probably the cleanest breakdown of agentic boundaries I’ve come across.
Out of curiosity, how are you handling that confirmation step in your stack - mostly polling/idempotency keys, or relying on signed webhooks?
That’s exactly the question — although we treat confirmation less as “polling vs signed webhooks” and more as an evidence problem.
A signed webhook can prove a provider emitted an event. An idempotency key can bind an attempt. A state check can tell us what the resource looks like now. But none of those automatically proves the full chain from this specific dispatch to the claimed downstream consequence.
So OpsWatch uses whatever authoritative observation the downstream system exposes — provider events, resource-state reconciliation, receipts, or combinations of them — and binds that evidence back to the specific attempt.
The rule is simple: the evidence never gets to claim more than it proves.
That’s also where DENIED_UNRESOLVED came from. If authority is revoked after dispatch but we can’t prove the downstream consequence was prevented, we preserve the uncertainty rather than quietly turning an internal “denied” into “nothing happened.”
Authorization → Dispatch → Execution → Downstream Confirmation.
Each boundary has to earn its own claim.
You sound like you’ve already run into this boundary in practice. If you have a real Stripe/AWS workflow where you think the chain is solid, I’d be interested in putting one bounded case against it. Those are usually much more revealing than discussing the architecture in the abstract.