We Made Our Agent "Remember More." It Got Worse, Not Better.
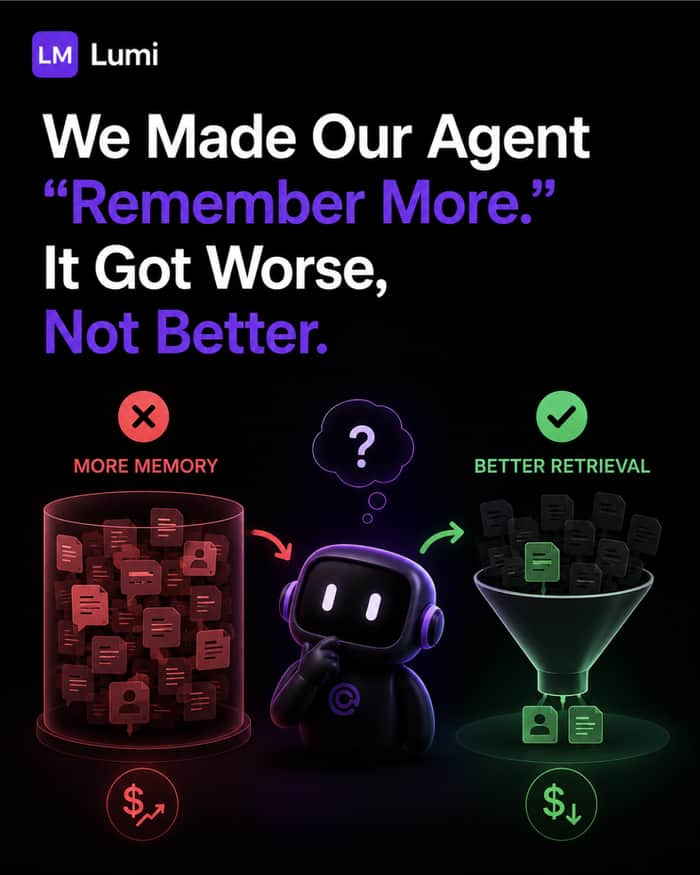
Our fix for "the agent forgot something important" used to always be the same: store more, retrieve more. Increase how much context gets pulled in per call. Felt like the obvious lever.
It backfired twice over. Cost scaled with every message since we were reprocessing the growing history each call, not just the new part. And accuracy actually dropped, not despite more context, because of it, models pay less attention to stuff buried in the middle of a long context window than to what's at the start or end.
The fix wasn't more memory. It was better retrieval. Store everything, sure. But stop dumping the whole history in, pull in only what's relevant to the specific step. Smaller, sharper context beat bigger context on both cost and accuracy at the same time, we expected a tradeoff, not a win on both.
Anyone else learn this one the hard way before switching to retrieval over accumulation?

The “more memory made it worse” result is interesting.
Did better retrieval improve both cost and task accuracy consistently?