Your Sol Quota Is Dying on File Reads. Luna Should Be Doing That.
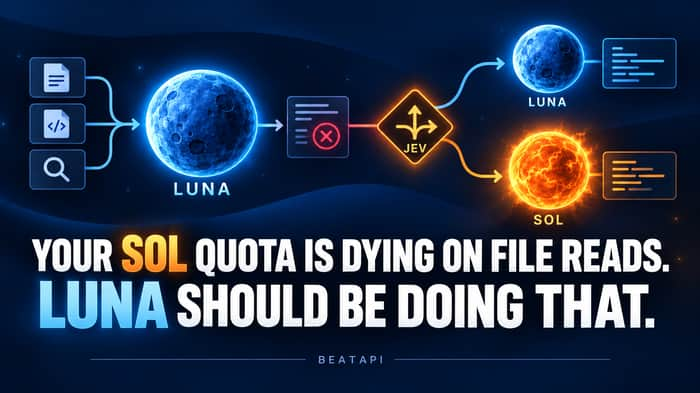
A question we are working through at BeatAPI: when Codex finds new evidence halfway through a coding task, what should decide whether the next step stays on Luna or moves to Sol?
The tempting answer is a fixed rule: send file reads and searches to Luna, send difficult edits to Sol. That is useful, but a failing test can reveal a shared authentication dependency after the work has started. The rule did not know that in advance.
I wrote up three increasingly flexible options below. This is a design pattern, not a measured claim about savings on our own task set. I would love to hear which signal other builders use to decide when a coding agent should switch models.
The quick fix: change the default
Open Codex and select gpt-6-luna. To keep it as your default, put model = "gpt-6-luna" in your Codex config. This takes seconds. It also sends planning and architecture work to Luna, including work you may still want Sol to handle. That is why the default switch is the blunt option.
The better split: Luna scouts, Sol keeps the main thread
Keep the main task on Sol. Give reads, searches, and the first look at a code path to a read-only Luna subagent. A personal custom agent file at ~/.codex/agents/scout.toml can contain:
name = "scout"
description = "Read-only first pass for files, searches, and code paths."
model = "gpt-6-luna"
model_reasoning_effort = "high"
sandbox_mode = "read-only"
developer_instructions = "Read and summarize relevant files. Report evidence and uncertainty. Do not edit files or make deployment decisions."
Then ask Codex to use scout for that first pass. The Codex subagents guide explains custom agent files: https://learn.chatgpt.com/docs/agent-configuration/subagents
This split is better than a global default, but the rule is still one you wrote ahead of time. A failing test that reveals a shared authentication dependency will not reclassify itself.
The typed checkpoint: ask JEV about the next step
BeatAPI's Free JEV API accepts the state your workflow already has and returns a typed decision. It does not write a patch, grant deployment, or replace a human review. Your code decides what to do with the answer.
Call jev-1.13-free on POST /v1/systemone. The current free-call contract says input and output are $0, including at zero balance; before the first top-up, the account allows one successful request per minute. That is enough to wire a checkpoint, not a production throughput guarantee.
Example request:
{
"model": "jev-1.13-free",
"state": {
"task": "Fix the failing test",
"observed_result": "The failure now traces through a shared authentication module",
"current_model": "gpt-6-luna"
},
"questions": {
"route": {
"type": "choice",
"instructions": "Which model should handle the next coding step?",
"criteria": {
"luna": "The remaining change is contained and can be checked locally",
"sol": "The next step requires tracing or changing shared behavior"
}
}
}
}
Read answers.route.choice, answers.route.probabilities, and answers.route.confidence. The JSON above is a request example, not a recorded result for this task. If the answer is missing or below your threshold, collect more evidence and keep the next action conservative.
The open-source jev-router shows a narrower, turn-level routing pattern inside Codex. It needs that project's own key; a BeatAPI key does not drop into it. https://github.com/gargpratyush/jev-router
What evidence would make you switch a coding agent from a smaller model to a stronger one mid-task? The API and request contract are here if you want to test this pattern: https://beatapi.io/jev-api and https://docs.beatapi.io/decisions#free-calls

Good
Really good writeup, thanks for sharing it. What's the next thing you're planning to try here?
The scout pattern is the right shape — a read-only first pass that reports what it found before anything changes.
The harder question is what constitutes enough evidence to escalate. Useful signals we have found: the task touches more than one module boundary, the first pass surfaced a dependency the description did not mention, or the change requires reasoning about state across multiple steps. Single-file edits, formatting, and test scaffolding stay cheap.
We run a similar split at UtilitySEO with translation. Groq handles seven languages, and the cases where quality justifies a more expensive model are narrower than expected — most translation work is metadata and UI strings where fast and cheap wins. The exception is marketing copy where tone matters, and that distinction maps to your "contained change vs shared behavior" split.
The unexpected dependency is the tricky part for me. A task can look like a simple file read until the scout finds that it touches shared behavior. I hadn’t thought about translation in the same way. With marketing copy, do you start with the stronger model, or try the fast one first and switch when the tone feels off?
Honest answer: we start with the fast one and never switch. Our translation cron runs Groq across all seven languages unattended — no quality gate, no escalation trigger, no human review loop. The assumption is that for SEO content and tool descriptions, the fast model handles it well enough, and if something reads badly a user in that language would notice before we do.
The part we didn't build is exactly what you're asking about: a signal that says "this translation needs the expensive model." We don't have one. The risk is that we wouldn't know a bad German translation from a good one anyway, so an automated quality check would just be one model grading another, which is circular.
If I were building it now, I'd probably use the scout's own confidence score rather than trying to judge tone programmatically.
That still feels circular: the scout’s confidence is another model judgment, and fluent errors can look certain. A small native-speaker spot-check of high-traffic pages would give you real errors to base the escalation rule on.