AethelOCR
AI OCR for documents-audio-studies-intelligent insights
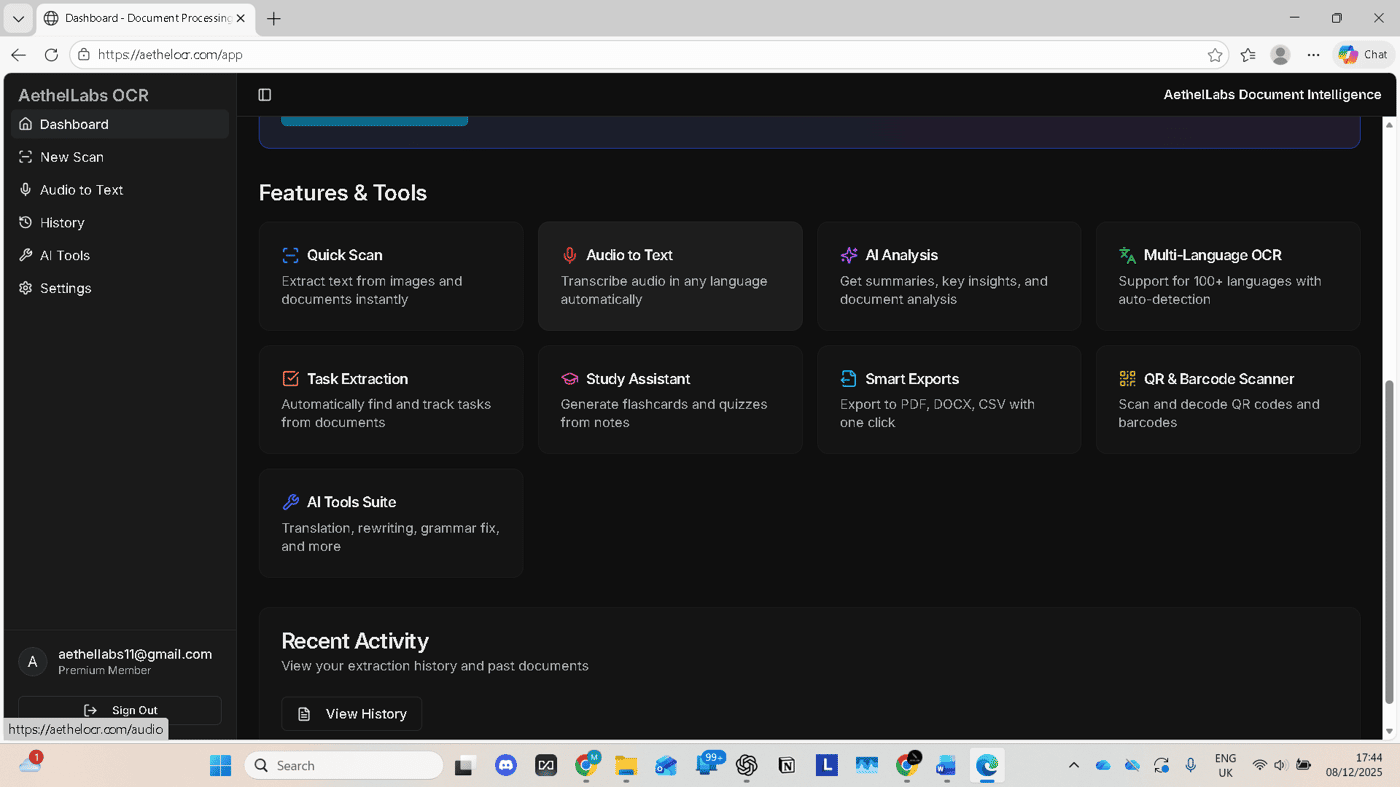
Sharing a few screenshots from AethelOCR — an AI OCR tool I built as a student + indie founder.
I built this after constantly working with PDFs, scanned documents, and audio files during studies and projects, where extracting text wasn’t enough — understanding and acting on it was the real challenge.
What’s shown in the screenshots:
• Uploading PDFs and images for OCR
• Clean text extraction results
• AI-generated summaries and study notes
• Automatic action-item extraction
• Simple, distraction-free UI
The goal was to keep it practical and fast, not overloaded with features.
I’m curious:
• Which part of this flow feels most useful?
• What looks unnecessary?
• If you were using this, what would you expect next?
Happy to hear honest feedback or answer questions.


Hey Indie Hackers 👋
I’m a student founder and I’ve been working on AethelOCR — an AI-powered OCR tool I built to handle the constant flood of PDFs, scanned documents, and audio files I deal with during studies and projects.
Most OCR tools stop at text extraction.
I wanted something that actually helps you understand and use the content.
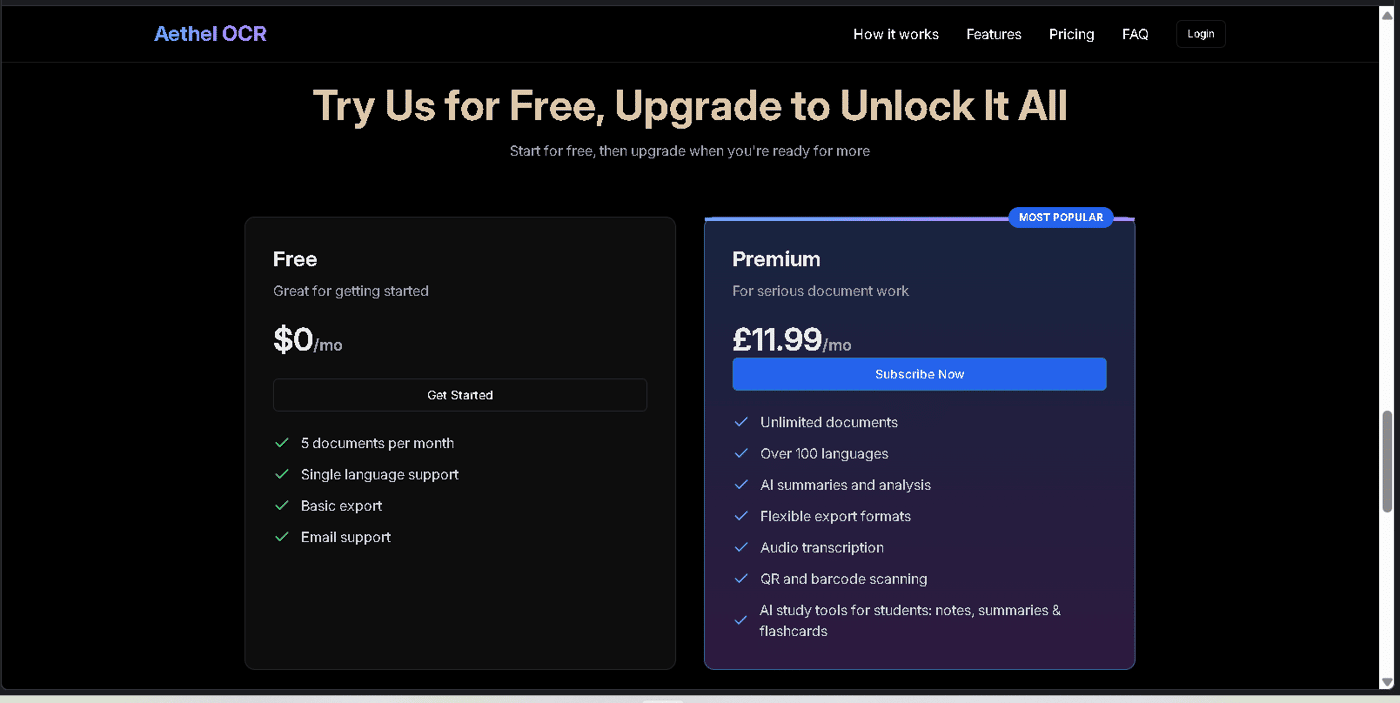
What AethelOCR does:
• Extracts text from PDFs and images
• Transcribes audio files
• Generates AI summaries and study notes
• Pulls out action items automatically
• Supports multiple languages
I’ve added a short demo video above showing the full flow from upload to results.
This started as a learning project, but it’s now fully functional and live.
I’d really appreciate feedback from other builders on:
• Use cases I should focus on
• Features that matter most
• Where you’d take this next
Happy to answer any questions.
Comment